#sre
3 skills & prompts · 0 tools · 1 MCP servers · 4 articles
Skills & prompts
eng-runbook
服务概述 + alerts 表 + dashboards + 操作命令 + on-call + 事故清单
site-reliability
Use when establishing reliability practice. Covers SLOs and error budgets, capacity planning, graceful degradation, load shedding, retry and timeout policy, and the arithmetic of availability. Trigger on "what slo should we set", "how many nines can we promise", "retries are caus
incident-postmortem-writer
Turns incident notes and timelines into a blameless postmortem with impact, root cause, timeline, what went well and action items. Use when the user needs to write up an outage, a failed deploy, a data problem or a security incident.
MCP servers
Reliability intelligence: production incidents, risk register, controls catalog, knowledge graph.
Articles
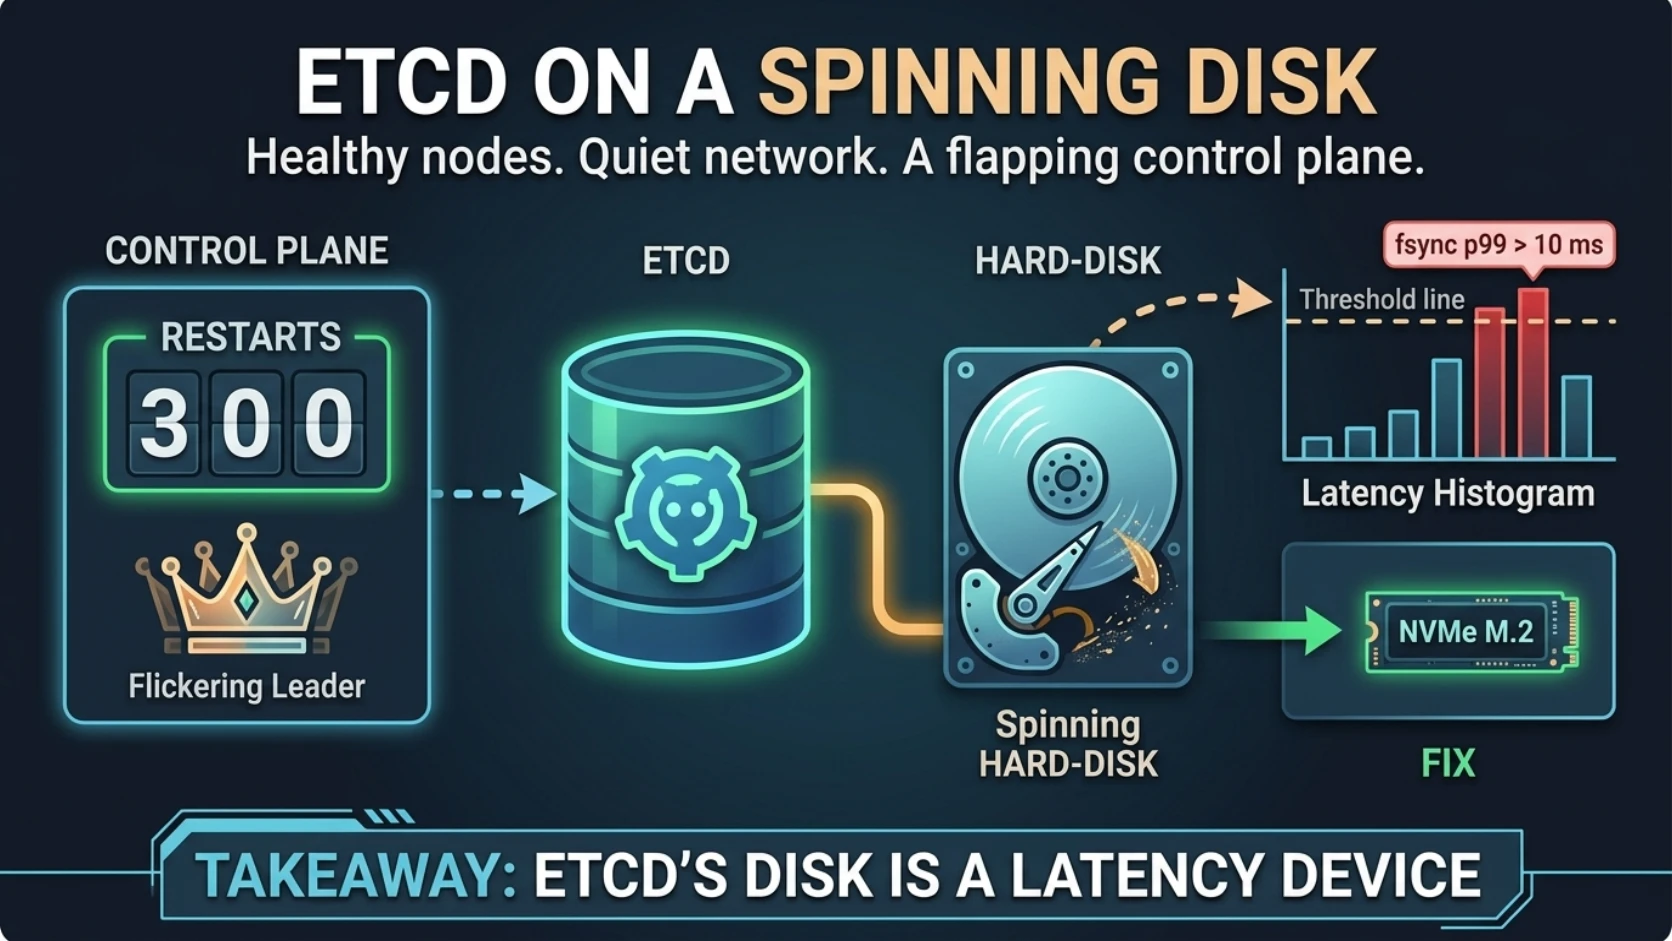
The control plane was flapping because of a spinning disk
Healthy nodes, a quiet network, 300 restarts in three days, and a latency budget measured in milliseconds
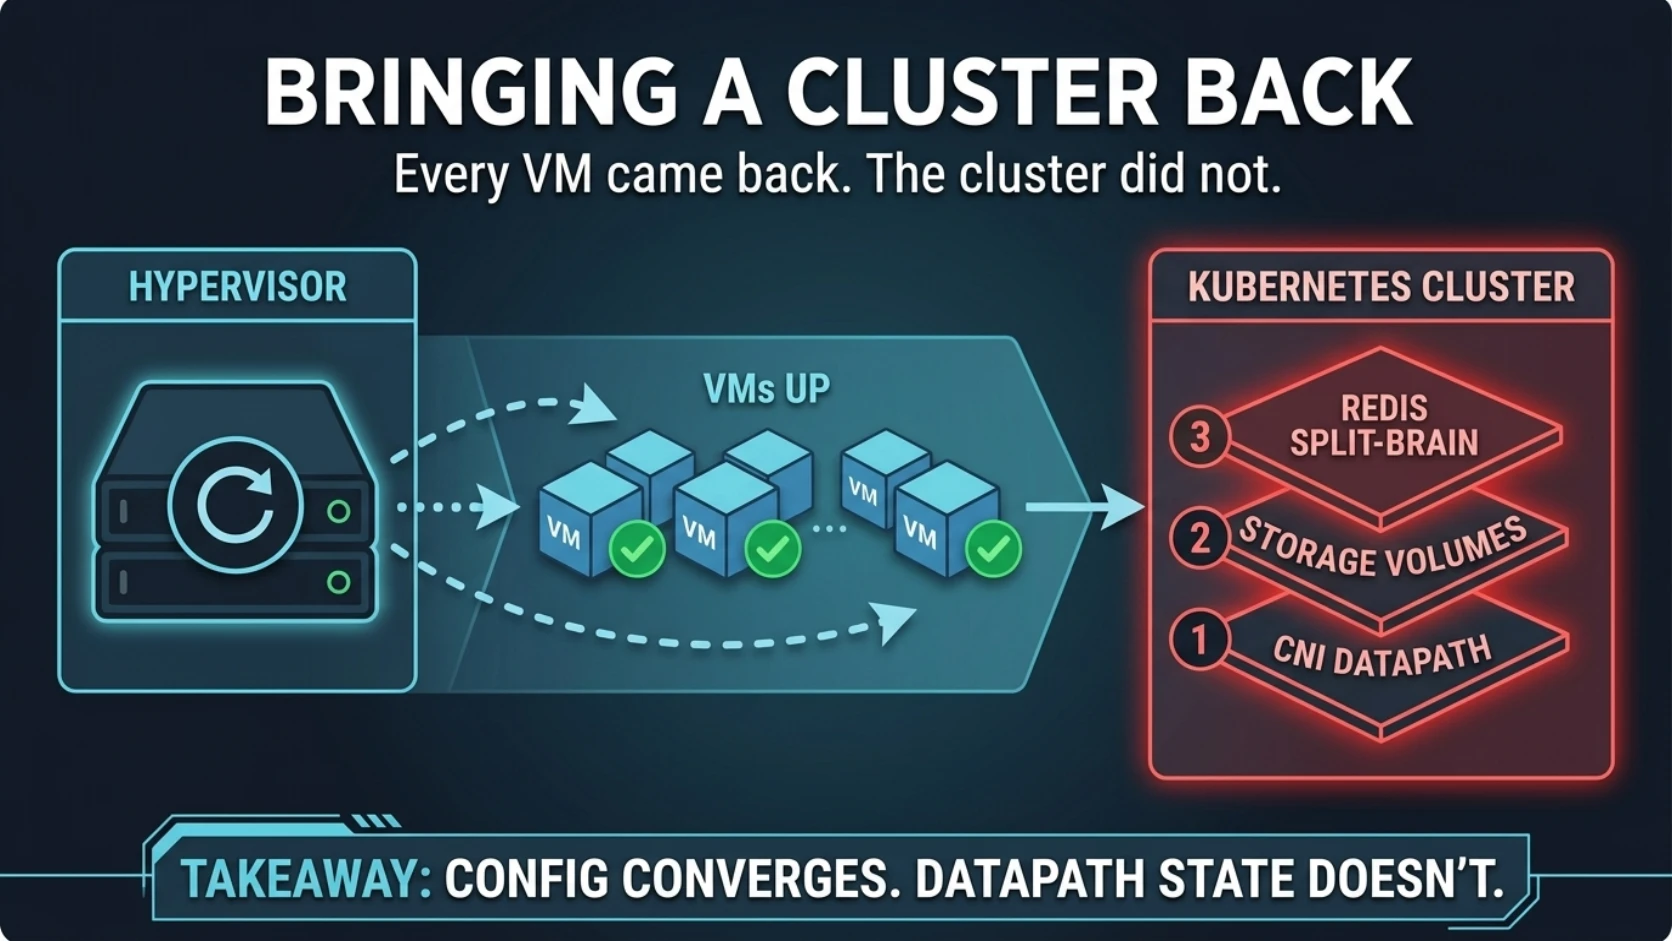
Bringing a cluster back after the host rebooted
Every VM came back. The cluster did not. Declarative systems converge on config, and the datapath isn't config.
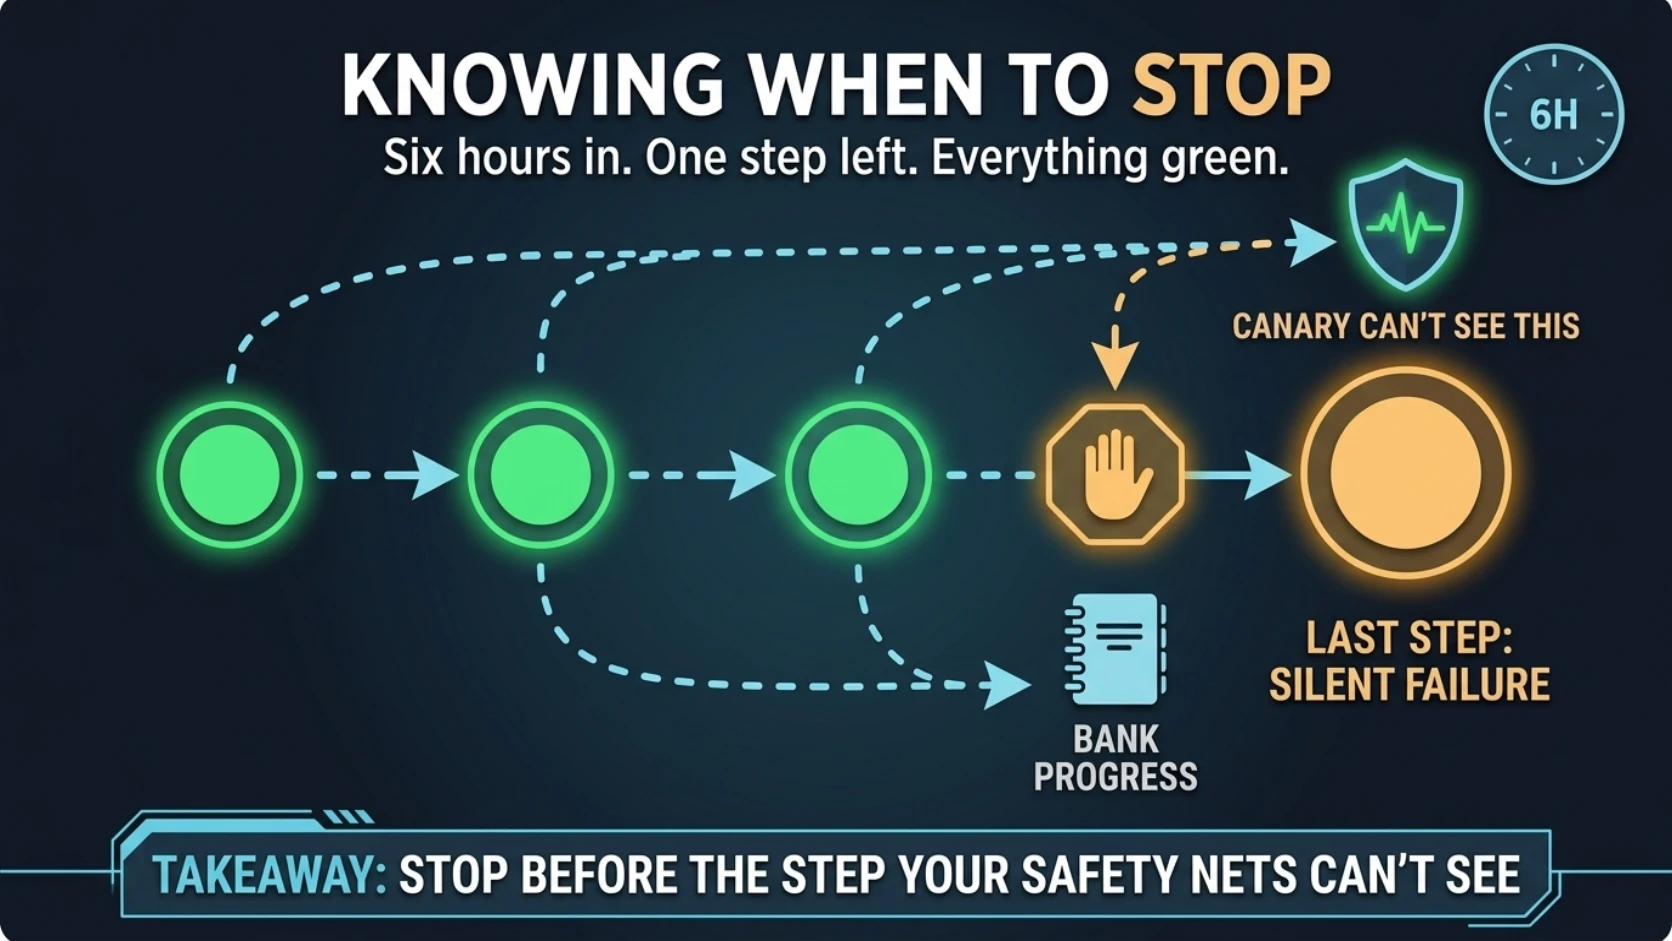
Knowing when to stop
Six hours in, one step left, everything green, and the incident that didn't happen
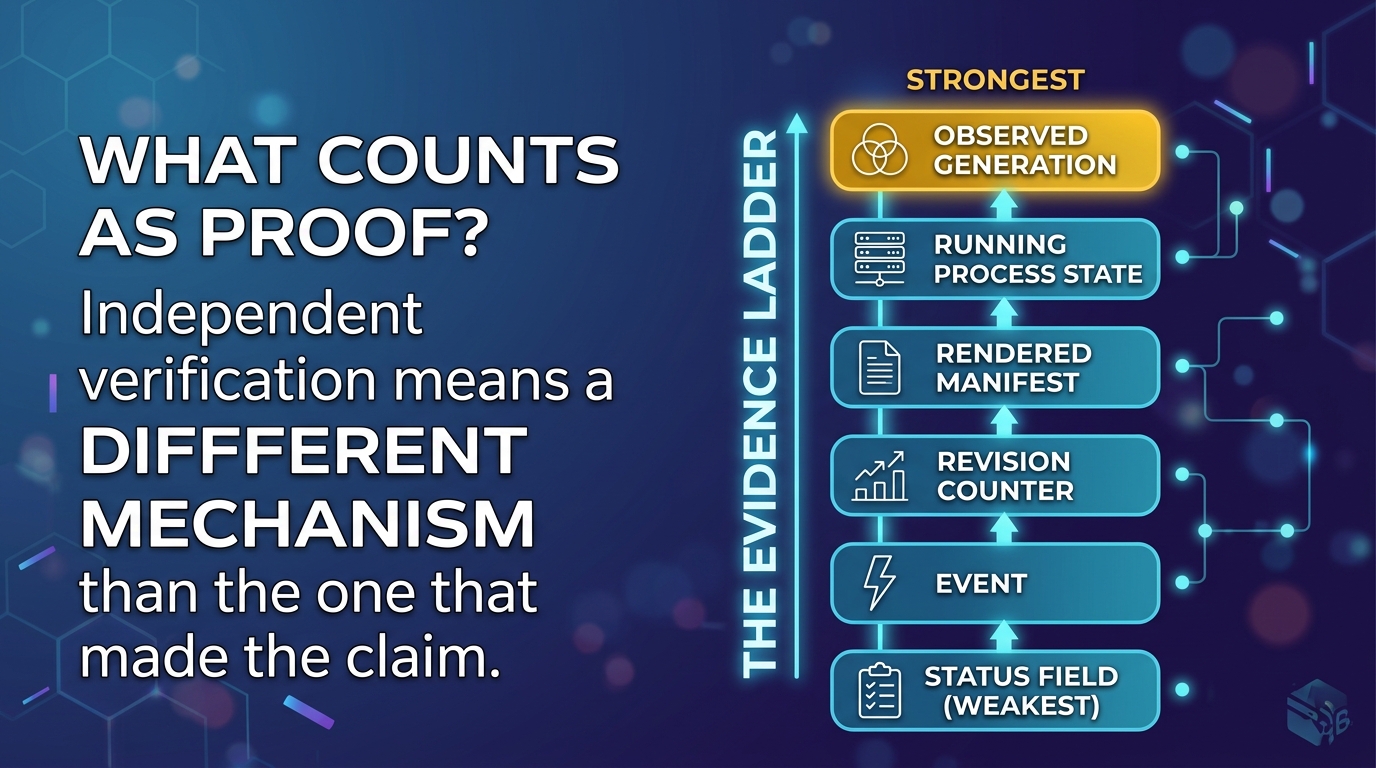
What counts as proof
"Verify your work" isn't an instruction. It's a mood. Here's the version that's an instruction. Verify with a different mechanism than the one that made the claim.