#incident-response
5 articles
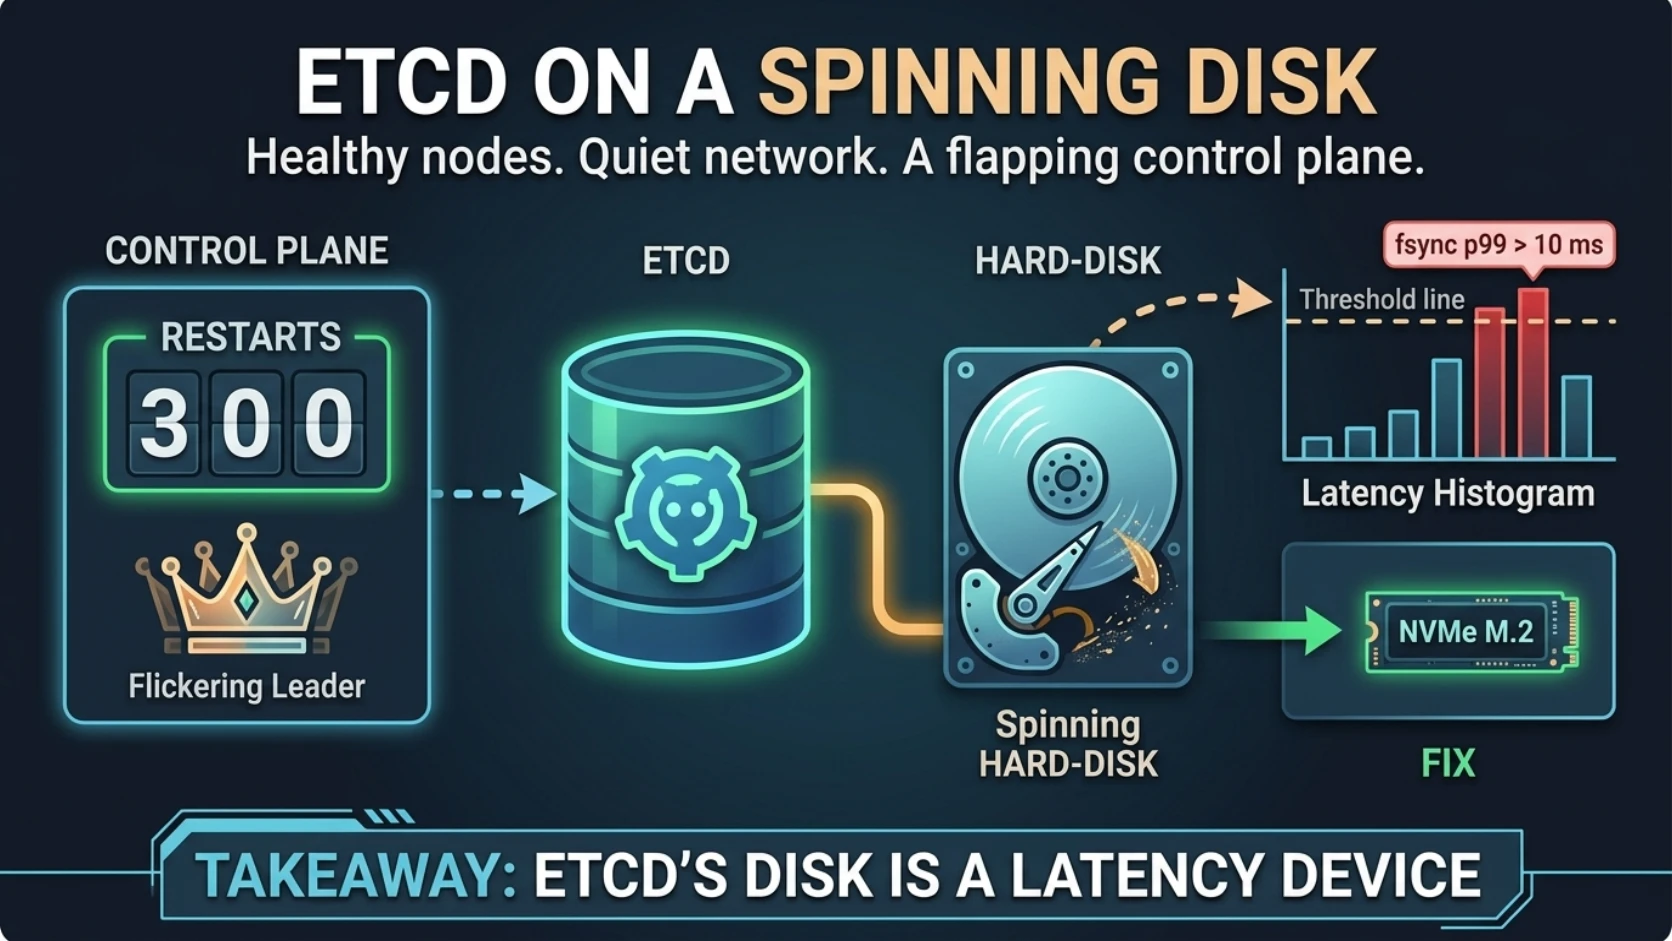
The control plane was flapping because of a spinning disk
Healthy nodes, a quiet network, 300 restarts in three days, and a latency budget measured in milliseconds
LLM Mart
· Sep 29, 2026
15
views
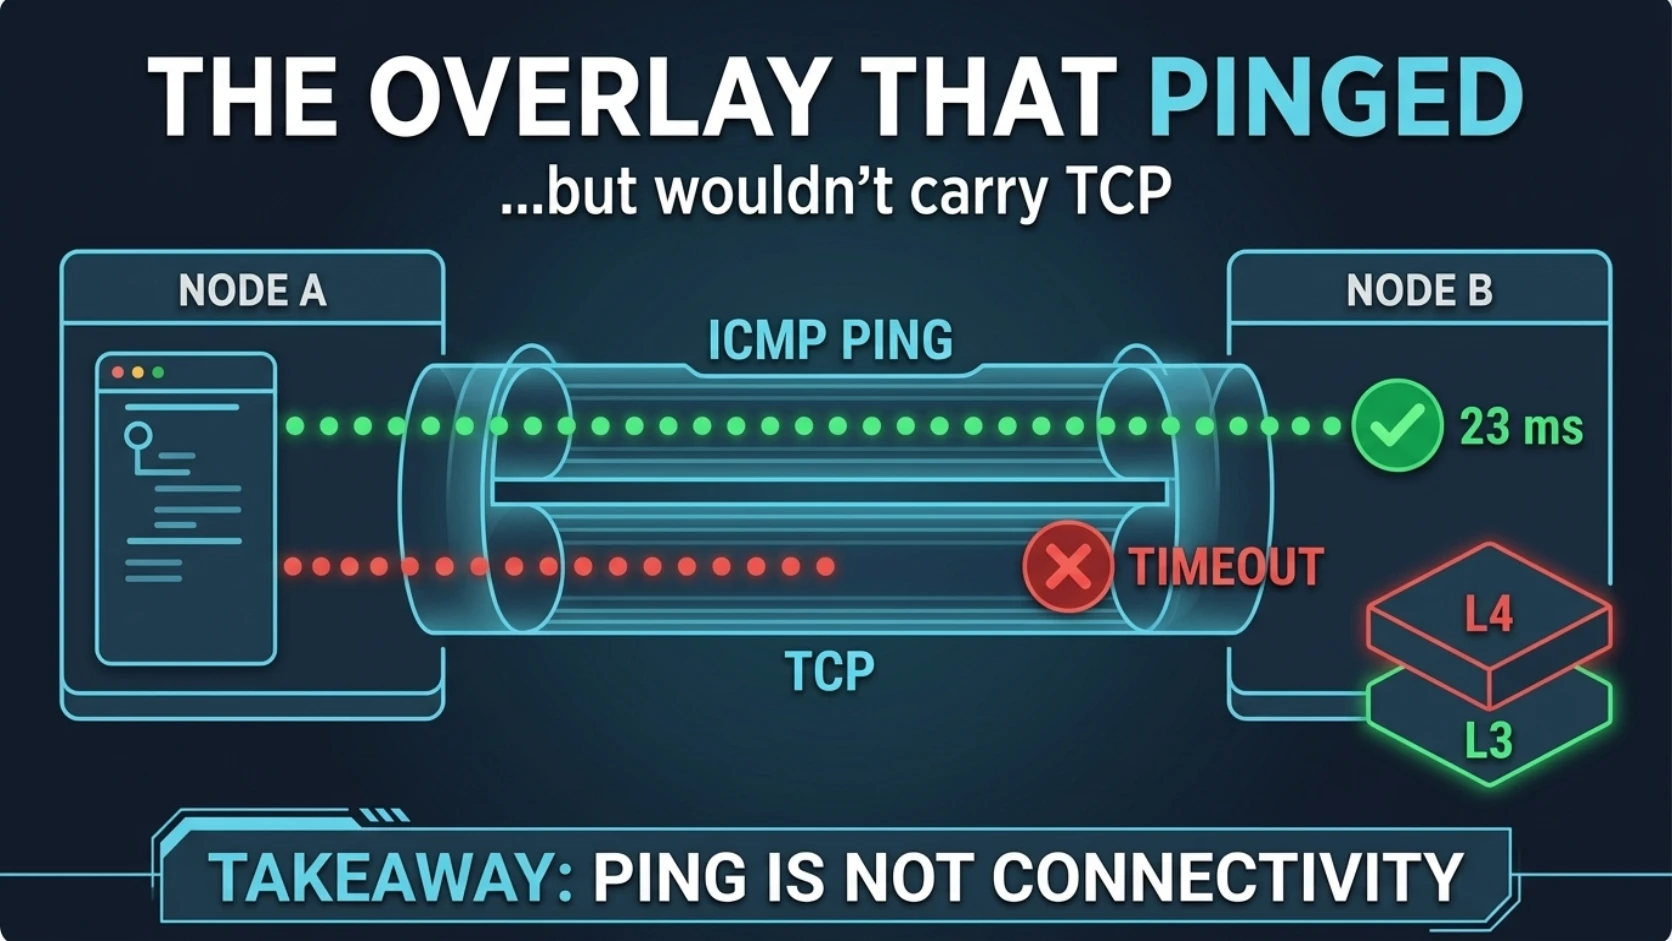
The overlay that pinged but wouldn't carry TCP
Discovery worked. Ping worked. Every TCP connection timed out, and later the tunnel only worked when someone had a terminal open.
LLM Mart
· Sep 28, 2026
14
views
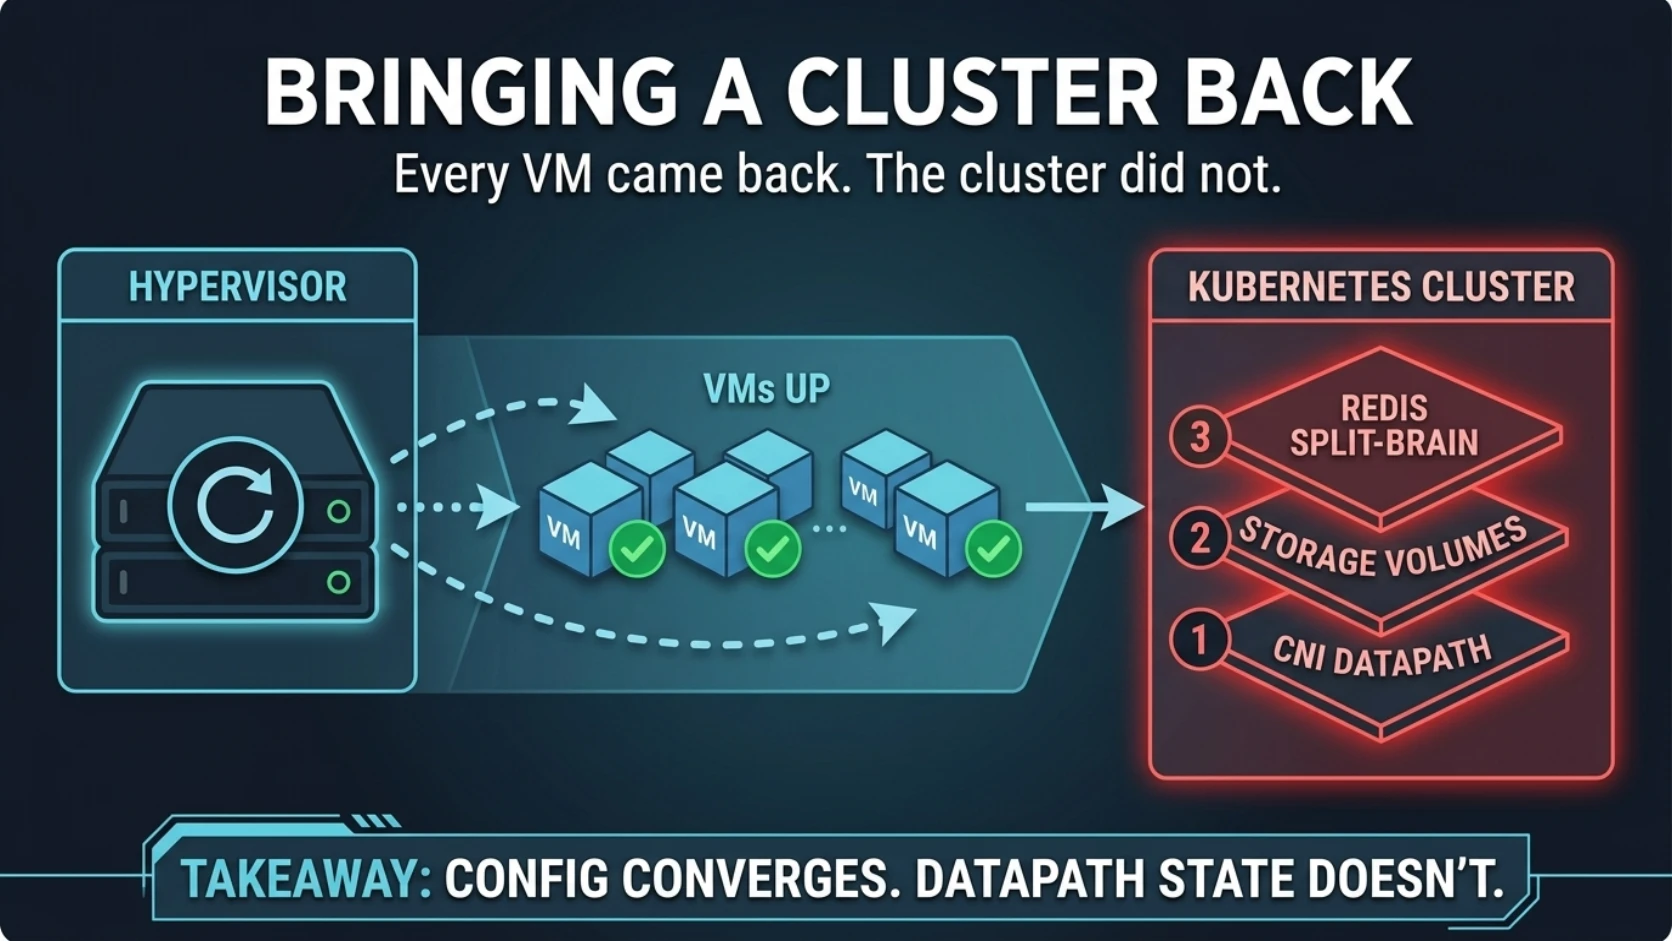
Bringing a cluster back after the host rebooted
Every VM came back. The cluster did not. Declarative systems converge on config, and the datapath isn't config.
LLM Mart
· Sep 27, 2026
8
views
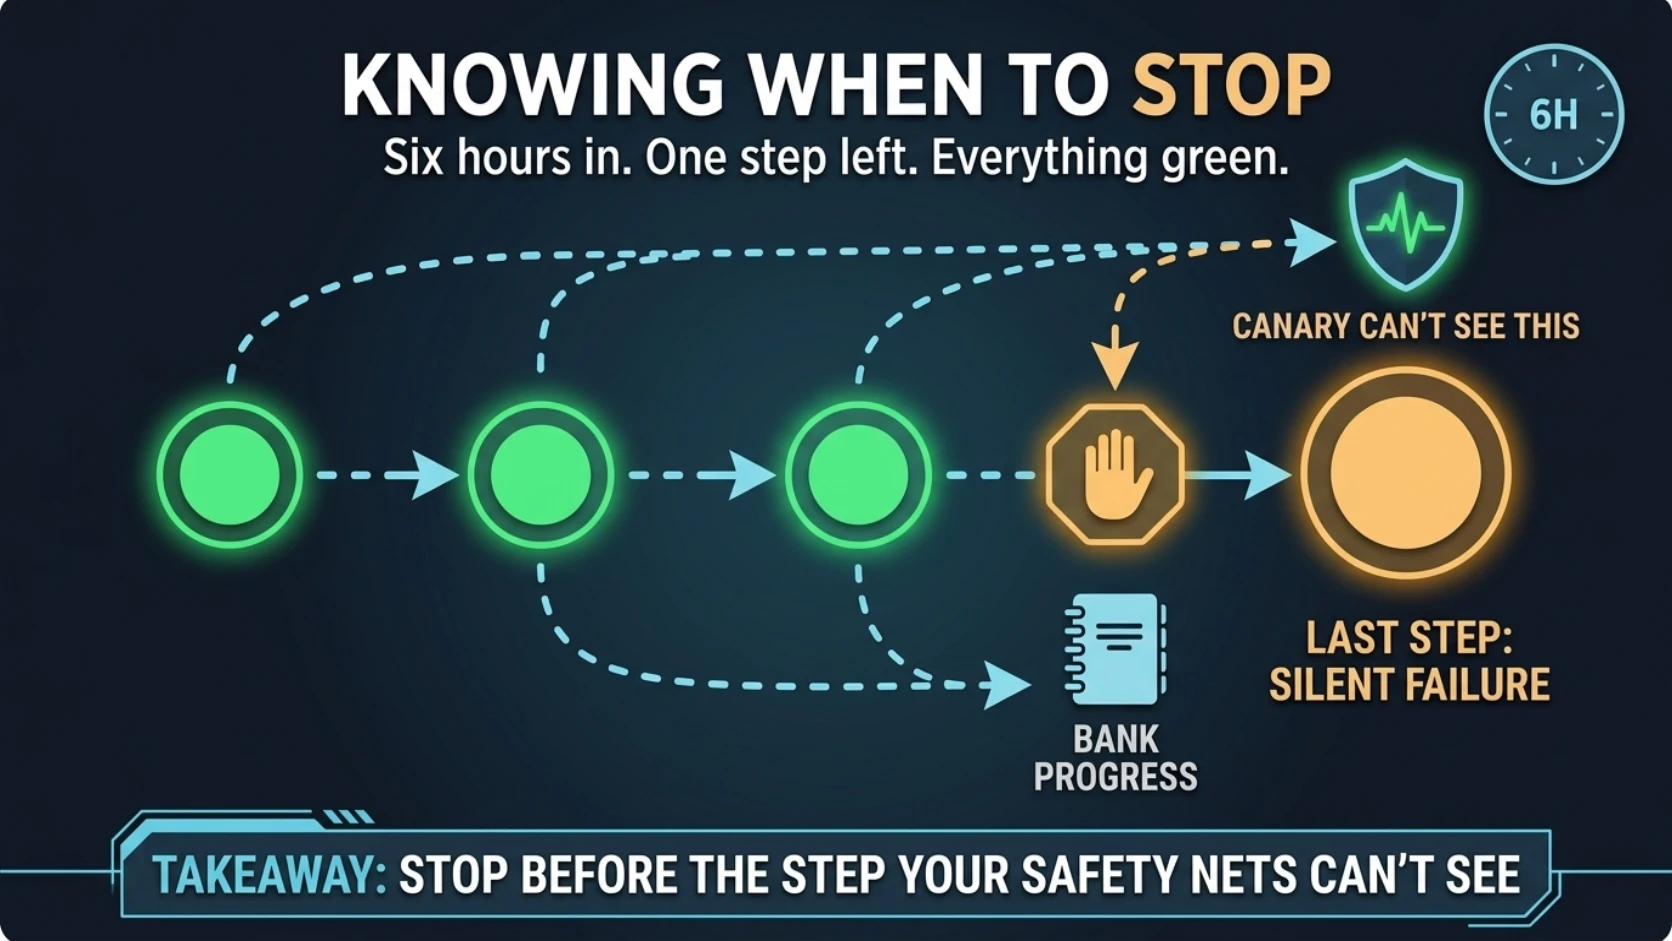
Knowing when to stop
Six hours in, one step left, everything green, and the incident that didn't happen
LLM Mart
· Sep 24, 2026
9
views
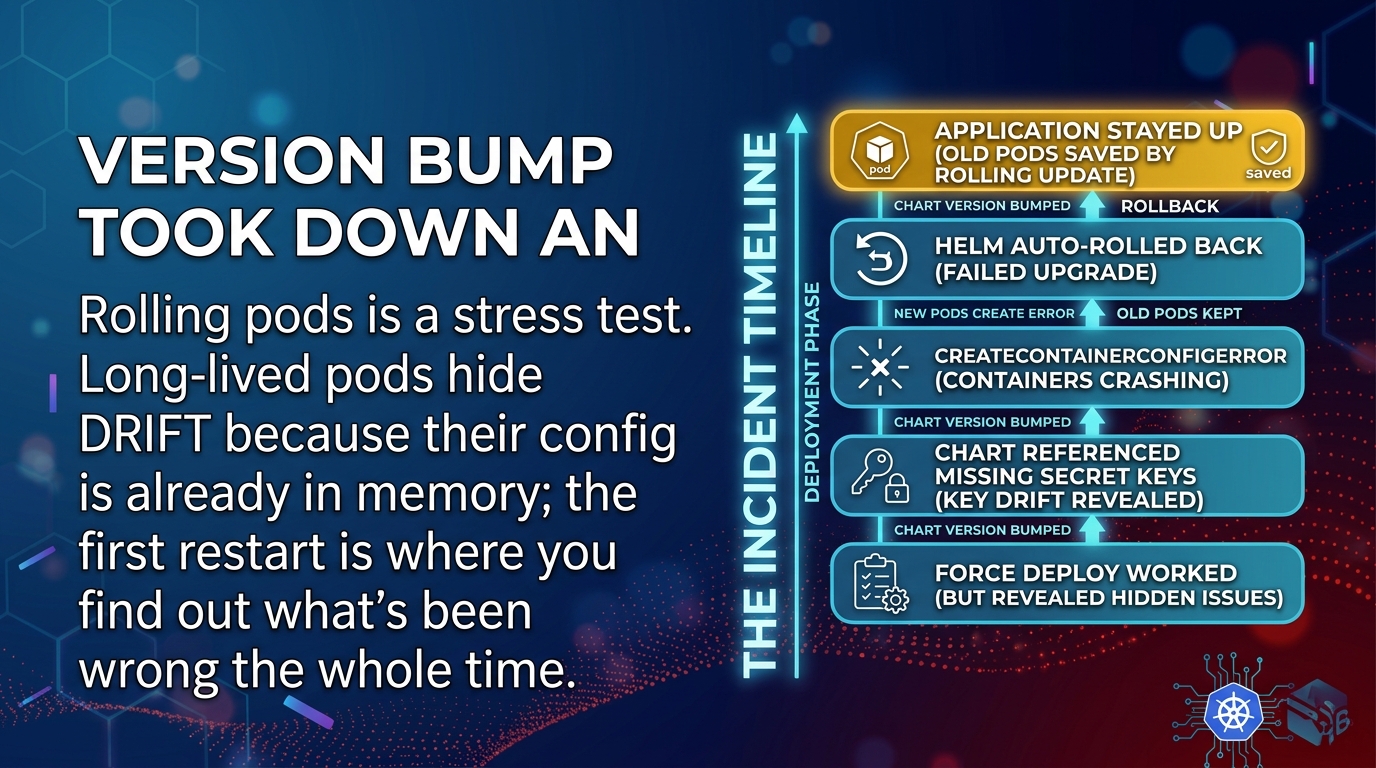
The version bump that took down an app (and how it self-healed)
One character of YAML, four pods that never started, and two safety nets I didn't know were holding. Every restart is an audit. Schedule them before they schedule you.
LLM Mart
· Aug 19, 2026
30
views