#prompt-engineering

Prompt engineering, tested: six tricks, 411 answers, scored by code
We ran six popular prompting techniques against developer tasks on three models and scored every answer with code. Three helped everywhere, one did nothing, two depended on the model. Here are the prompts, the numbers, and a script to test your own.
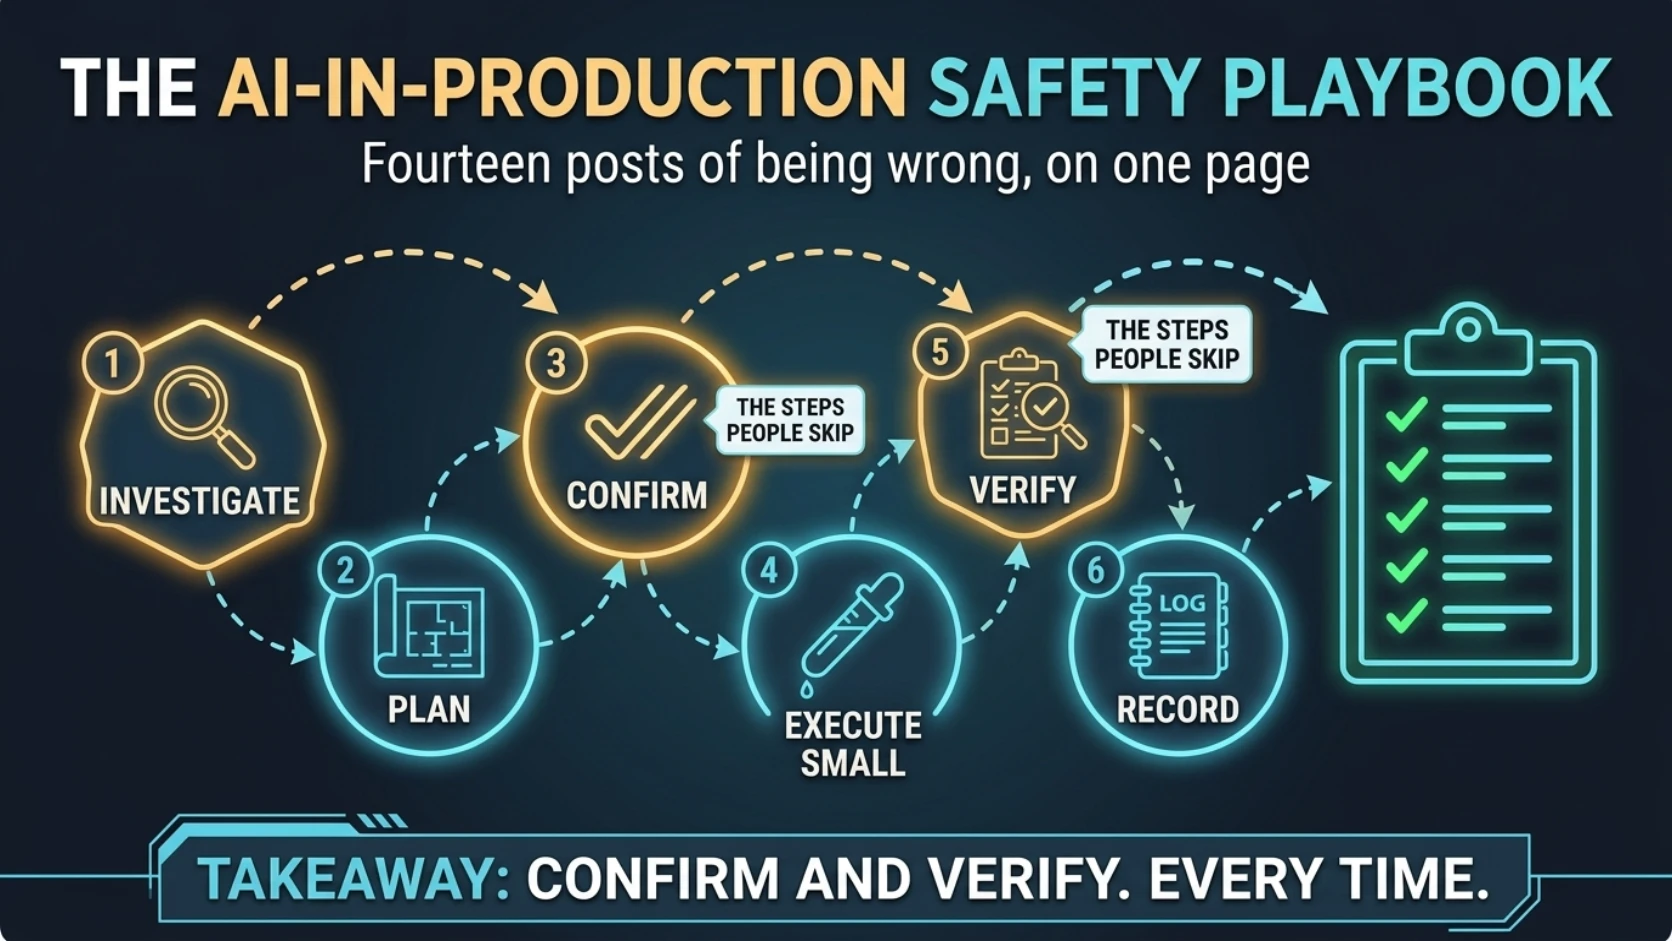
The AI-in-production safety playbook
Fourteen posts of being wrong in production, compressed to checkboxes
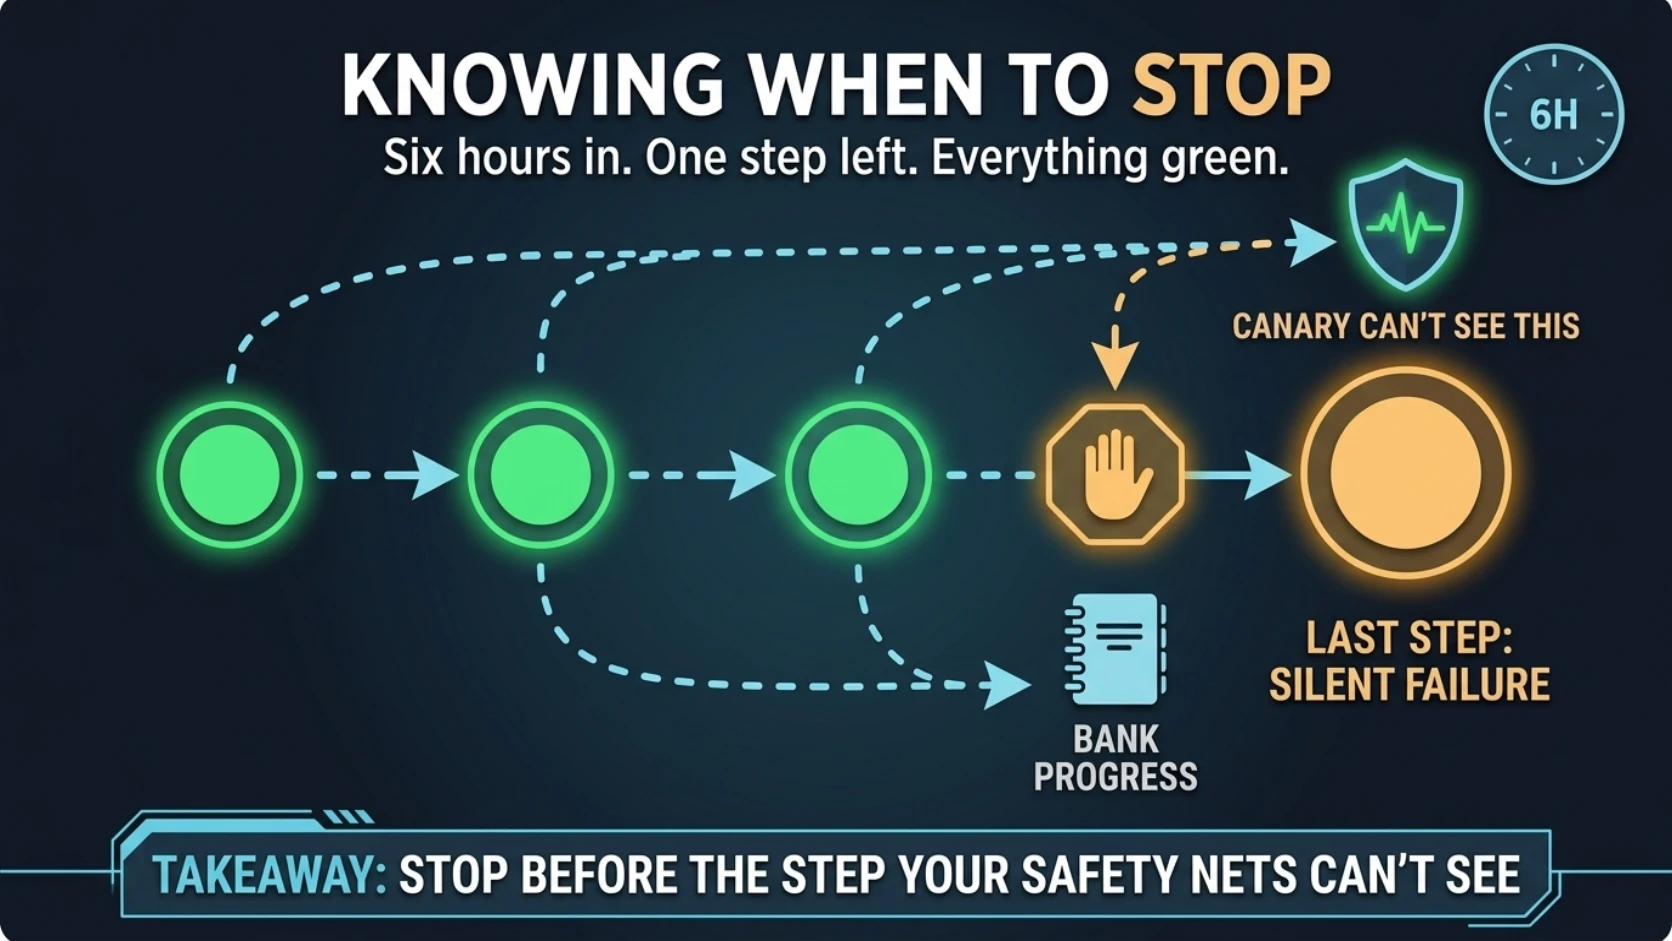
Knowing when to stop
Six hours in, one step left, everything green, and the incident that didn't happen
Prompt testing: build a lightweight eval set
A prompt that works once isn't a quality system. Five cases, an observable rubric, and a regression set will tell you whether a change helped.
How to Write Better AI Prompts: A Practical Framework
Better prompts aren't magic wording. They're short briefs that hand the model a task, the context it can't infer, the limits, and a quality bar.
Ship a prompt like code: a five-case eval harness you can build in an hour
You wouldn't ship a function you ran once. Here's the smallest evaluation setup that catches real regressions — five cases, three graders, and a rule for when to add a sixth.
The instruction file is the highest-leverage file in your repo
AGENTS.md, CLAUDE.md, copilot-instructions.md and .cursor/rules all solve the same problem. Most of them are written badly. Here's what changes agent behaviour and what's decoration.
Prompt, skill, workflow, recipe, template, agent: a working taxonomy
The words are used interchangeably and they shouldn't be. Six categories, what actually distinguishes them, and how to tell which one you're holding.