Articles
Original writing on getting more out of AI tools.
Point your agent at the catalogue: the LLM Mart MCP server and API
The whole public catalogue is an MCP server and a REST API, so your agent can search skills, tools and slash-commands as native tools. Setup is one config block. Plus a private vault that carries your own prompts between machines.
AI content SEO: how to publish pages that earn their place
AI made publishing cheap, which is exactly the problem. What separates a page worth ranking from a competent summary of the first ten results.
Prompt testing: build a lightweight eval set
A prompt that works once isn't a quality system. Five cases, an observable rubric, and a regression set will tell you whether a change helped.
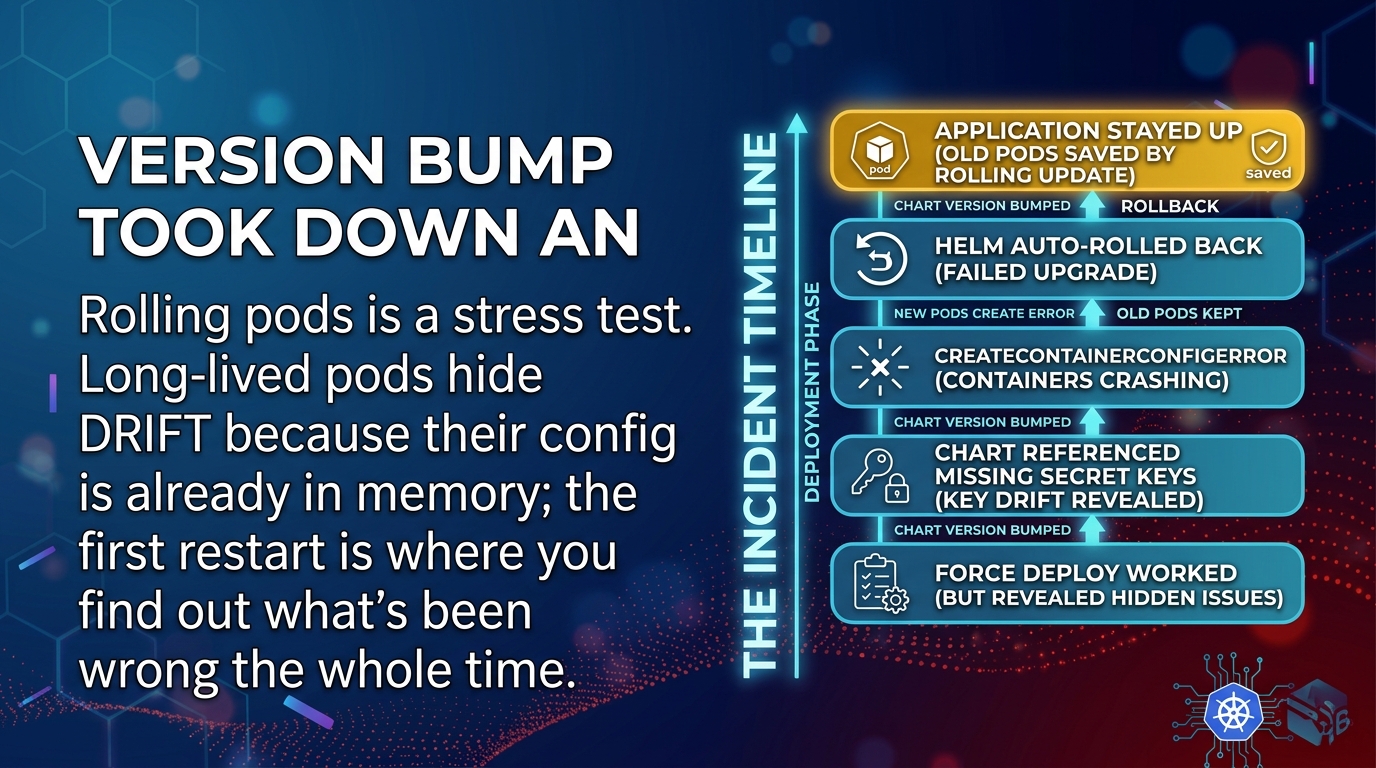
The version bump that took down an app (and how it self-healed)
One character of YAML, four pods that never started, and two safety nets I didn't know were holding. Every restart is an audit. Schedule them before they schedule you.
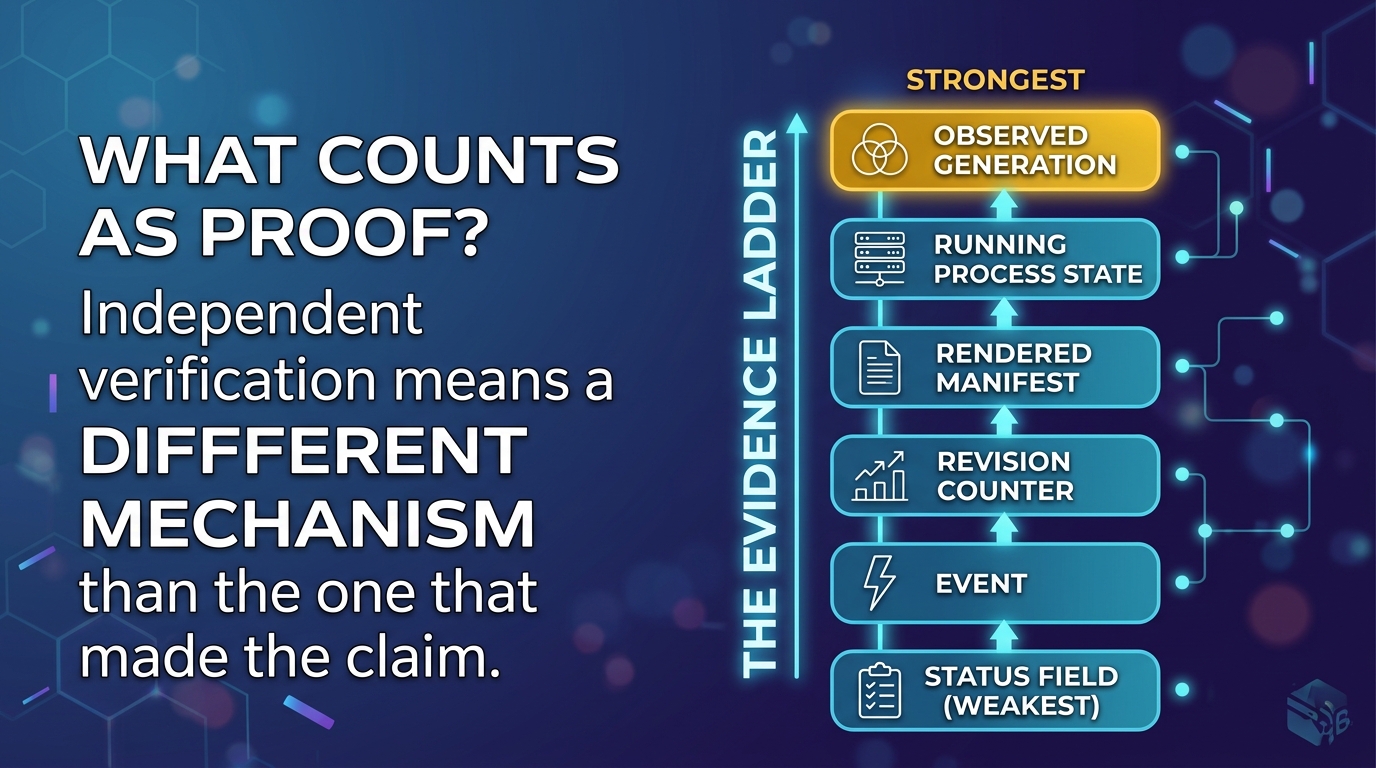
What counts as proof
"Verify your work" isn't an instruction. It's a mood. Here's the version that's an instruction. Verify with a different mechanism than the one that made the claim.
Prompt Testing: Build a Lightweight Eval Set
A prompt that works once may still fail in production. A lightweight eval set gives you repeatable cases, a clear rubric, and a way to see whether a prompt change actually improved the workflow.
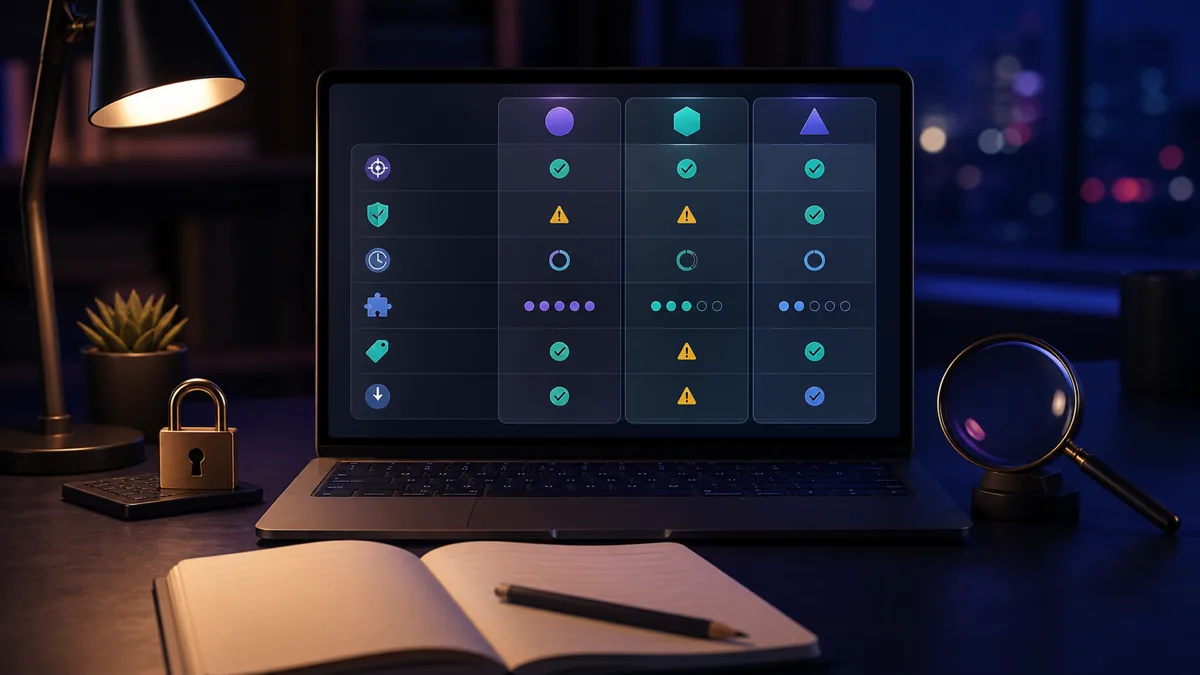
How to Choose an AI Tool: A Practical Evaluation Checklist
The best AI tool is not the one with the longest feature list. It is the one that solves a defined job reliably, fits the workflow, handles data appropriately, and remains useful after the novelty wears off.
How to Research with AI Without Losing the Source Trail
Use AI to speed research without losing trust. Learn to find primary sources, verify claims, preserve uncertainty, and keep an auditable source trail.
How to Write Better AI Prompts: A Practical Framework
Better prompts aren't magic wording. They're short briefs that hand the model a task, the context it can't infer, the limits, and a quality bar.
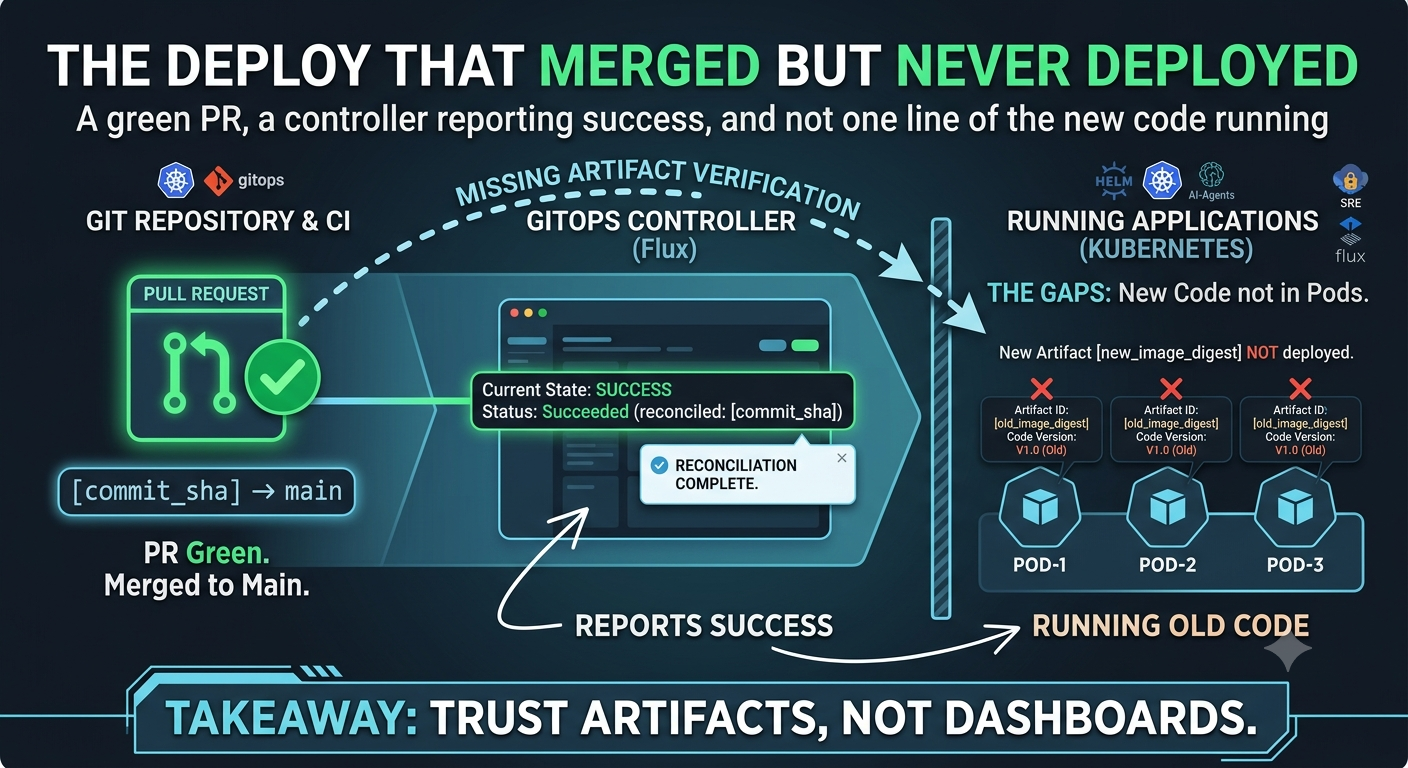
The deploy that merged but never deployed
A green PR, a controller reporting success, and not one line of the new code running
Ship a prompt like code: a five-case eval harness you can build in an hour
You wouldn't ship a function you ran once. Here's the smallest evaluation setup that catches real regressions — five cases, three graders, and a rule for when to add a sixth.
The instruction file is the highest-leverage file in your repo
AGENTS.md, CLAUDE.md, copilot-instructions.md and .cursor/rules all solve the same problem. Most of them are written badly. Here's what changes agent behaviour and what's decoration.
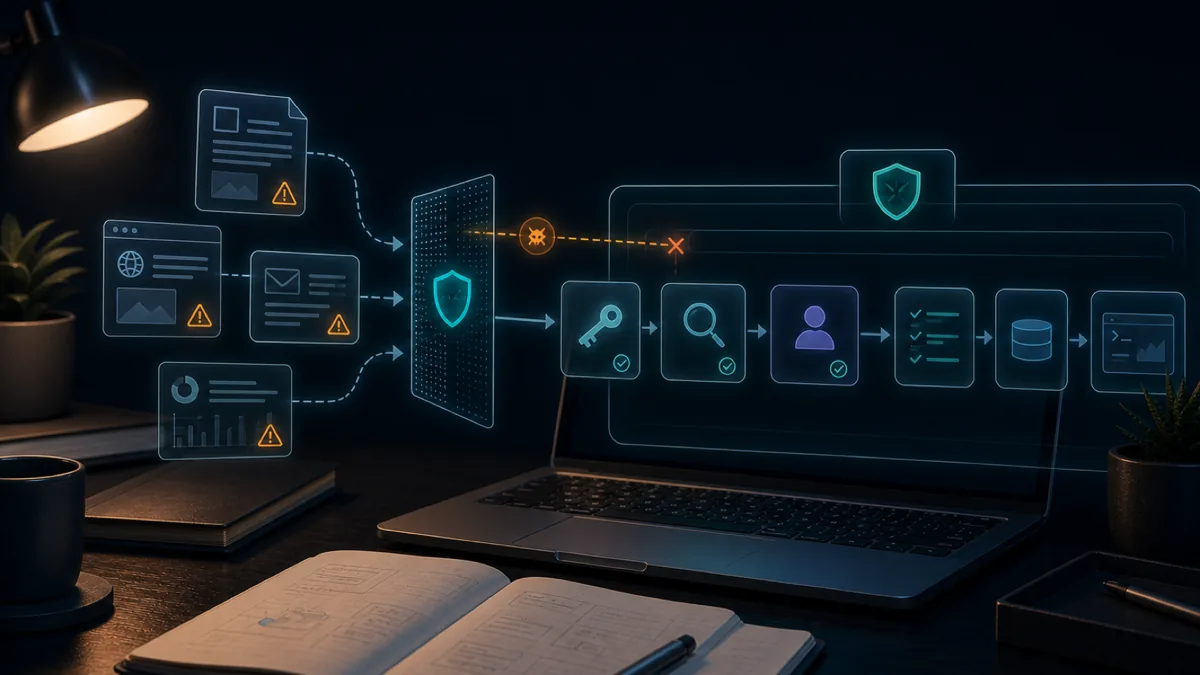
Prompt injection is not an XSS problem
Sanitizing output protects your page. It does nothing for an agent that reads a poisoned README and then runs a command. A practical model of the threat, and what actually helps.
Prompt, skill, workflow, recipe, template, agent: a working taxonomy
The words are used interchangeably and they shouldn't be. Six categories, what actually distinguishes them, and how to tell which one you're holding.
How to write a prompt you can reuse
Most prompts are lucky one-offs. The ones that keep working share a structure: an explicit role, a checklist of constraints, a worked example, and a self-check step. Here's how to build one.