Prompt Testing: Build a Lightweight Eval Set
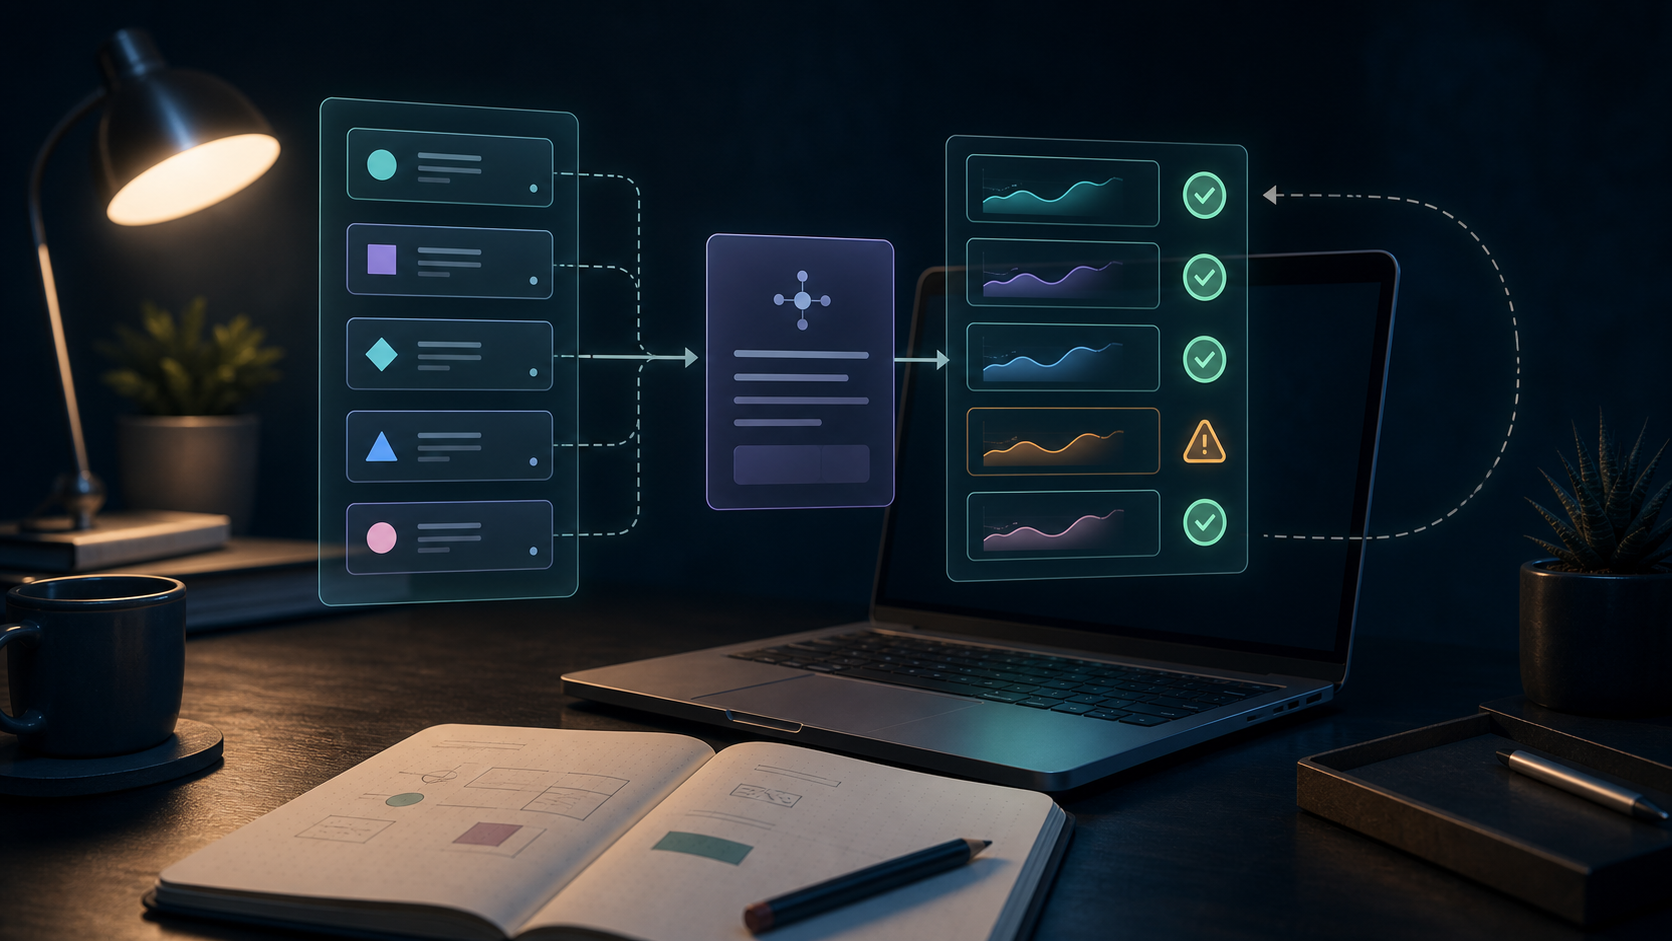
A prompt can look excellent in a chat and fail when the input changes. One lucky answer is not a quality system. If a prompt supports a real workflow, test it with the kinds of inputs it will actually receive.
What an eval set contains
Each case needs an input, expected behavior, pass criteria, and optional reference data. Also record the prompt, model, configuration, and test date for the run. The expected behavior matters: creative tasks may allow several answers, while extraction tasks may require a strict schema.
Start with five cases
Choose one normal case, two common variations, one messy case, and one case where the model should ask a question, mark uncertainty, or refuse. Add more as the workflow grows.
Include typos, missing fields, long documents, contradictory instructions, or mixed languages when those occur in production. The eval set should resemble the real job — not a curated demo.
Define pass and fail first
A useful rubric is observable:
- Extracts all required fields.
- Does not invent absent values.
- Uses valid JSON with required keys.
- Flags ambiguity instead of choosing silently.
- Meets the target length.
Use 0, 1, and 2 when binary scoring is too rigid. Keep a separate severe-error flag for failures that could cause harm or trigger an incorrect action.
Test one change at a time
Record the prompt, model, tools, input preprocessing, date, and result. If you change everything at once, you cannot tell what caused the improvement.
OpenAI's evaluation guidance follows the same pattern: define a task, run it against test inputs, then analyze the results and iterate. The same structure works in a spreadsheet.
Categorize failures
Track missing information, unsupported claims, wrong classifications, format errors, incomplete answers, unwanted instruction following, and unsafe actions. Failure categories tell you what to fix: a prompt that loses its format needs a schema, while one that invents values needs an explicit "mark unknown" rule.
Run regression checks
Run the same cases after every meaningful change to the prompt, model, model settings, retrieval data, tools, or preprocessing. A new prompt may improve the common case while breaking a rare one. Keep a small regression set for mistakes you never want to reintroduce. For tool-using systems, test missing documents, stale data, permission boundaries, and tool errors.
NIST's AI Risk Management Framework frames evaluation as part of risk management: measure what matters, then watch it over time. The same instinct applies to a prompt that feeds a daily workflow.
Evals turn vague concerns into repeatable tests and explicit thresholds. Start with five representative cases, define what good means, categorize failures, and keep the regressions. The goal is not perfect automation; it is fewer surprises tomorrow.
Next step: Save your first five test cases in LLM Mart as a reusable prompt evaluation workflow.
Sources
Comments (0)
Sign in to join the conversation.
No comments yet.