#kubernetes
3 skills & prompts · 7 tools · 6 MCP servers · 7 articles
Skills & prompts
cron-doctor
Diagnose and validate cron expressions before they ship. Catches the five silent death-traps: impossible dates that never fire, OR-semantics that fire too often, midnight spikes, uneven step drift, and leap-year February 29.
github-runner
Deploy, manage, and troubleshoot self-hosted GitHub Actions runners. Covers systemd service, Docker containers, Kubernetes (Actions Runner Controller), and the Scale Set Client. Use when setting up a CI runner, debugging registration failures, designing autoscaling, or hardening
kubernetes
Use when deploying to or debugging Kubernetes. Covers workload configuration, resource requests and limits, probes, rollout strategy, networking, and the failure modes that produce CrashLoopBackOff and OOMKilled. Trigger on "pod keeps restarting", "pod stuck in crashloopbackoff",
Tools
Secure, Fast, and Extensible Sandbox runtime for AI agents.
The open-source, multi-agent alternative to Claude Tag. @ any agent, wherever work happens, your agents work alongside your team and each other, learning as the…

MCP servers
vSphere with Tanzu (VKS): Namespace and TanzuKubernetesCluster lifecycle. Requires vSphere 8.x+.
Governed Kubernetes ops — 55 MCP tools with audit, budget, undo, risk-tier audit labels.
phpMyFAQ - Open Source FAQ web application for PHP 8.4+ and MySQL, PostgreSQL and other databases
MCP Server and CLI for Apache Spark History Server. Debug Spark applications from AI agents, scripts, or the terminal.
Create, read and edit architecture, flow and ER diagrams on a live canvas shared with your team.
Articles
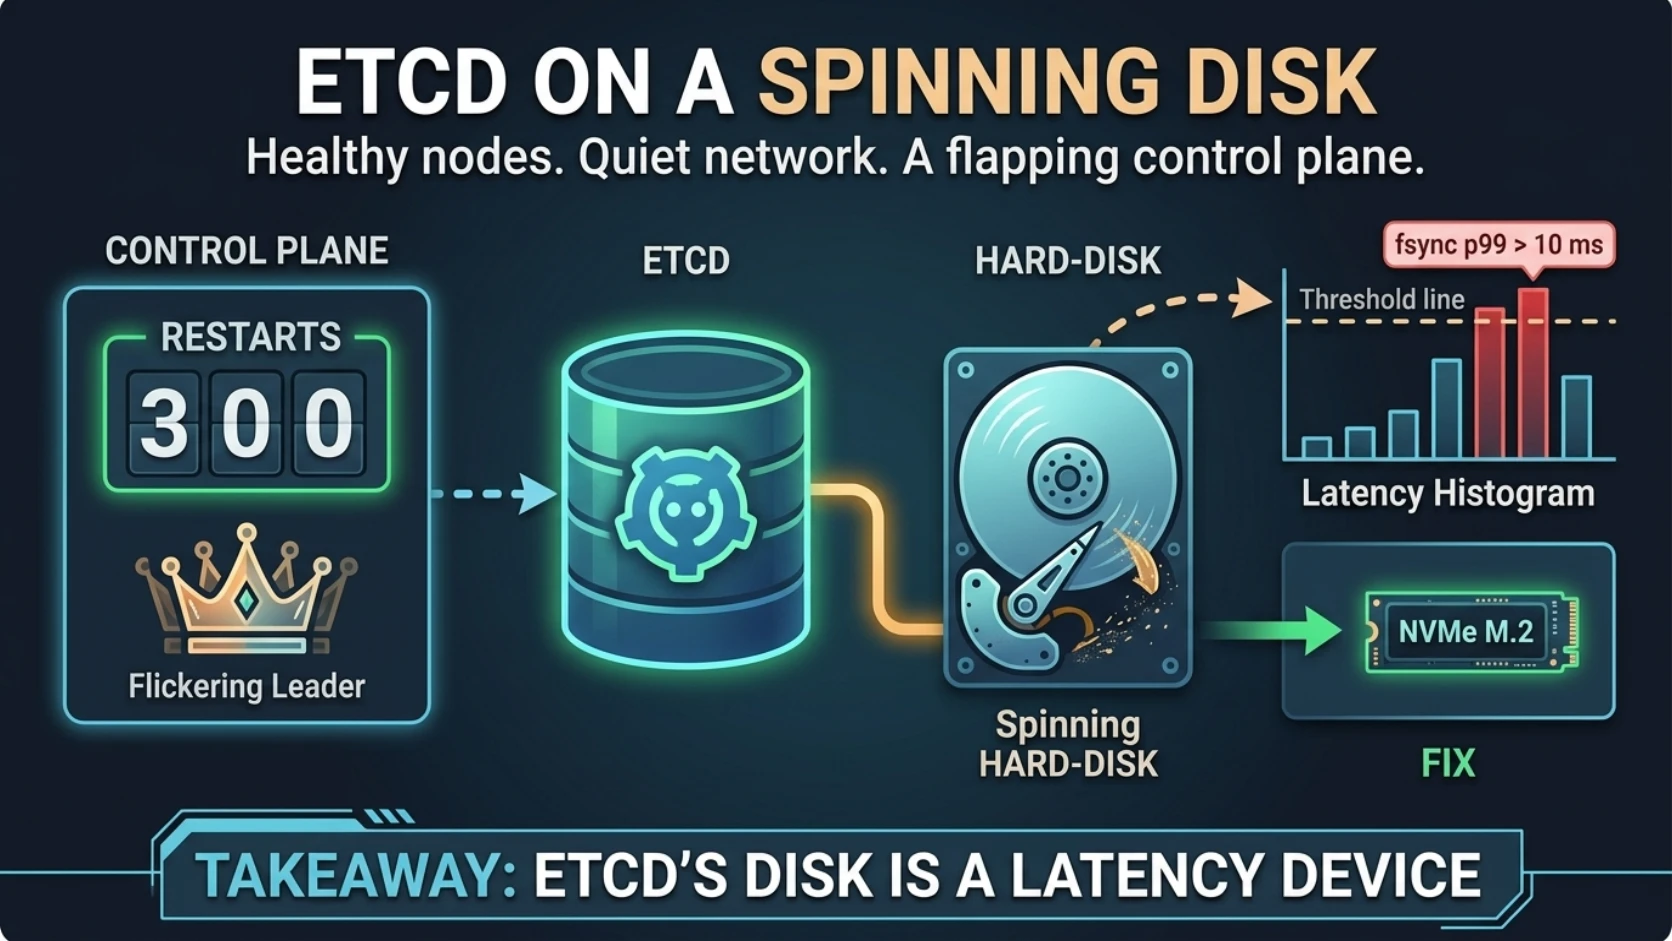
The control plane was flapping because of a spinning disk
Healthy nodes, a quiet network, 300 restarts in three days, and a latency budget measured in milliseconds
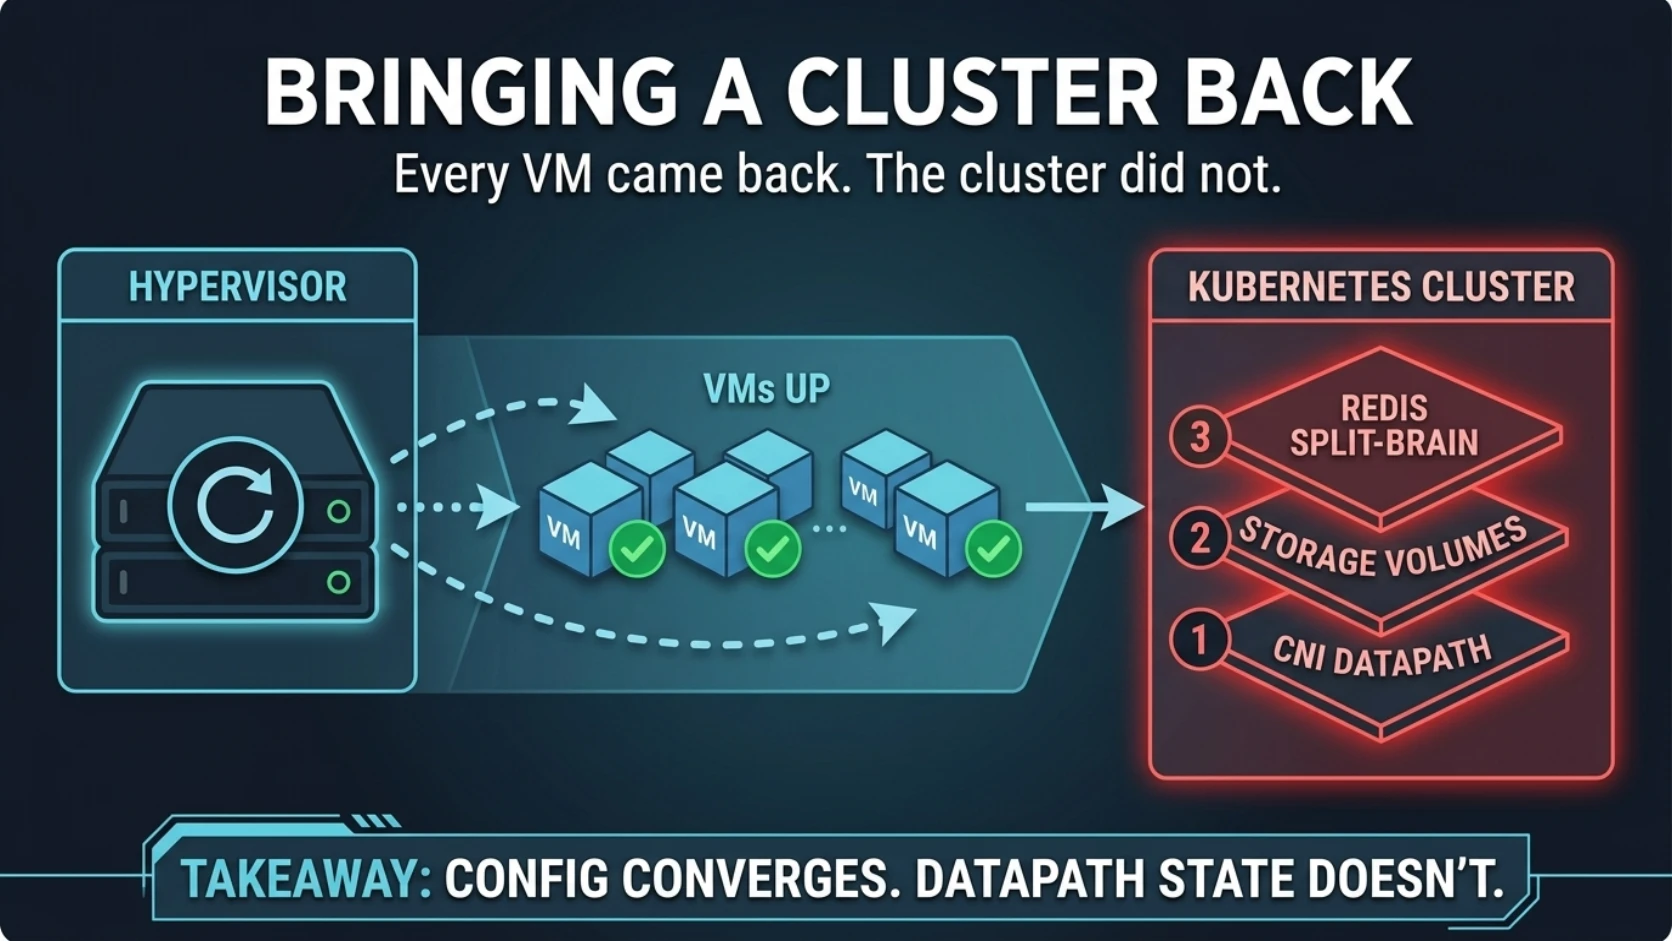
Bringing a cluster back after the host rebooted
Every VM came back. The cluster did not. Declarative systems converge on config, and the datapath isn't config.
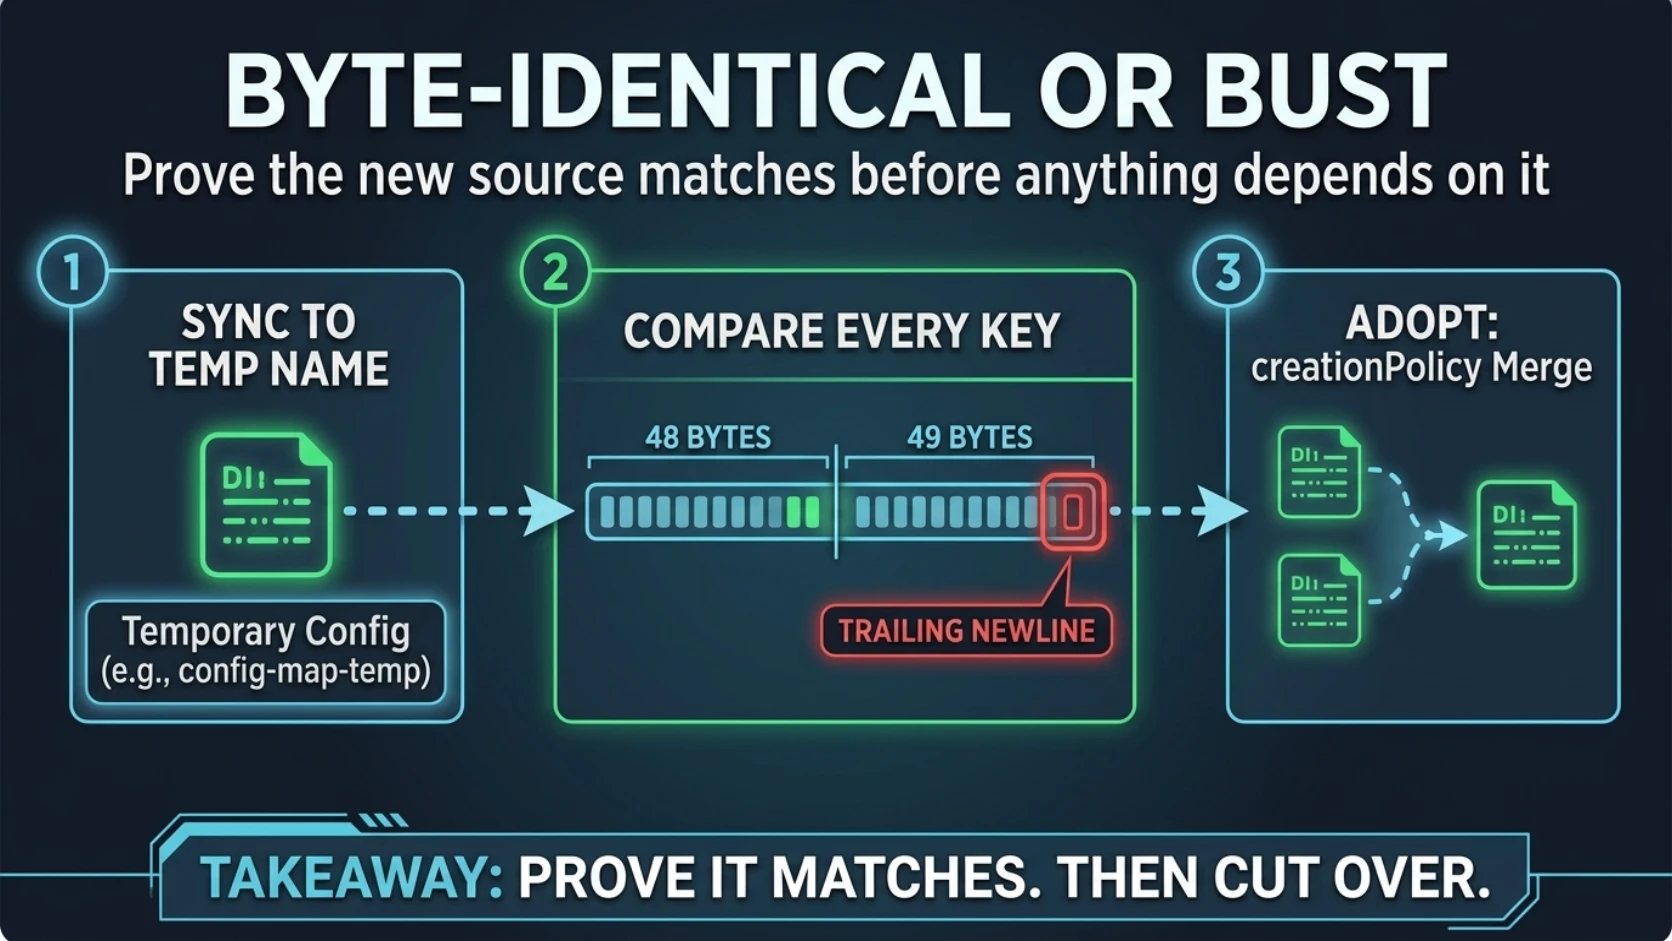
Byte-identical or bust
"Copy it over and switch the reference" is two steps, and the outage lives in the one nobody checks
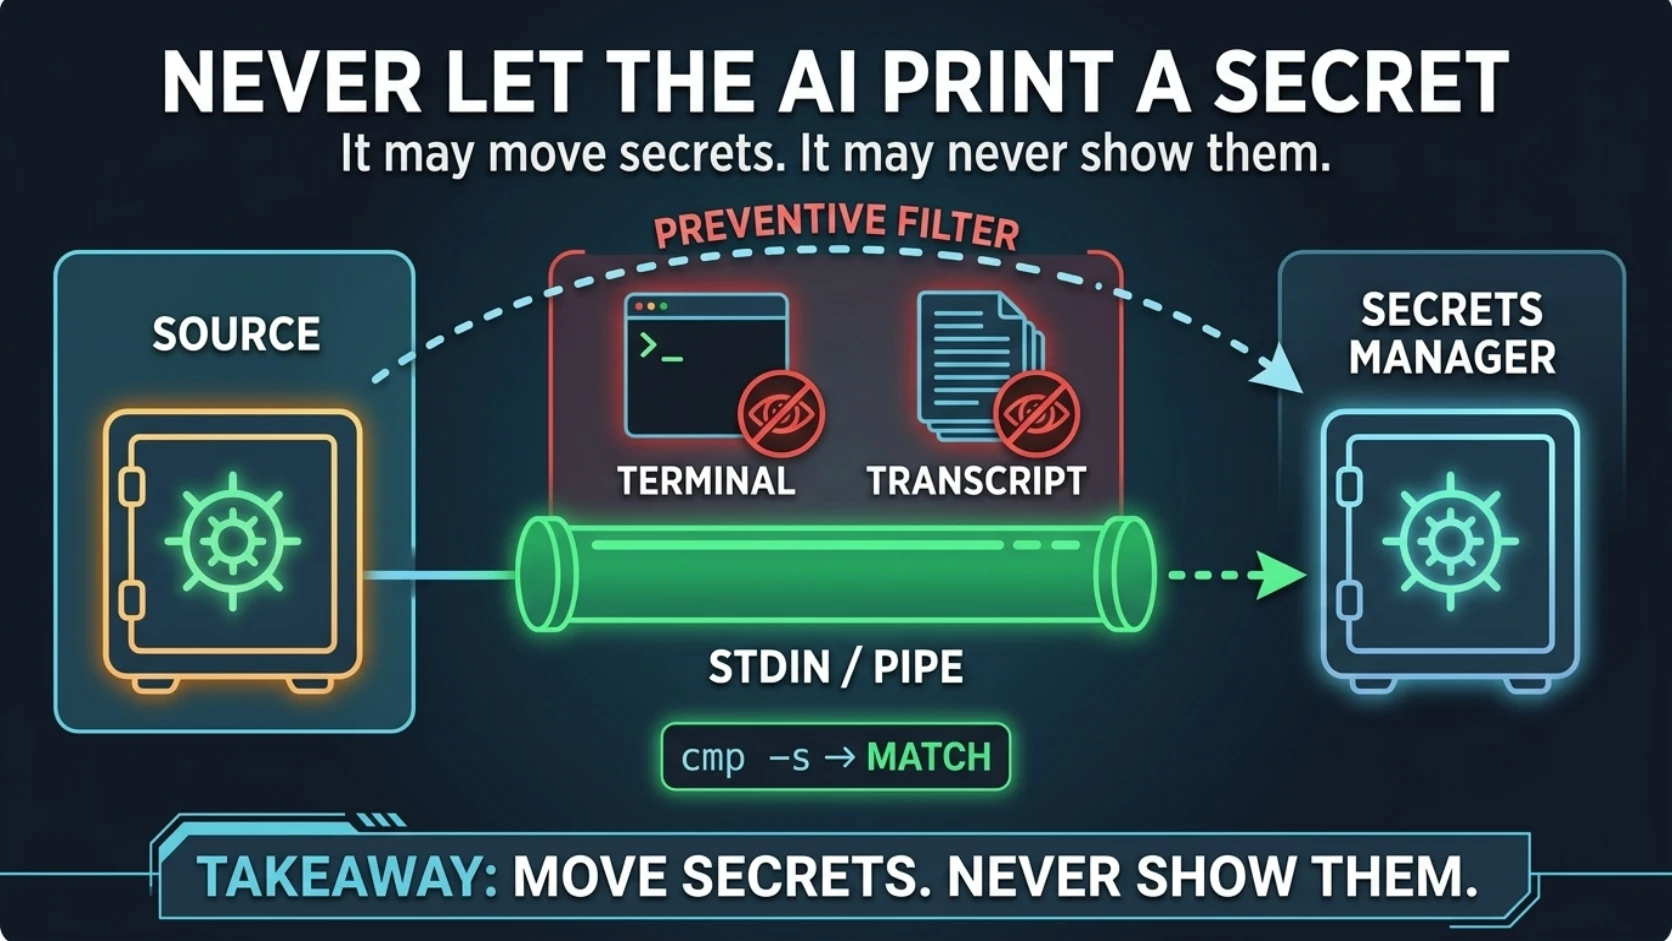
Never let the AI print a secret
The most important rule wasn't about what I could change. It was about what I was allowed to display.
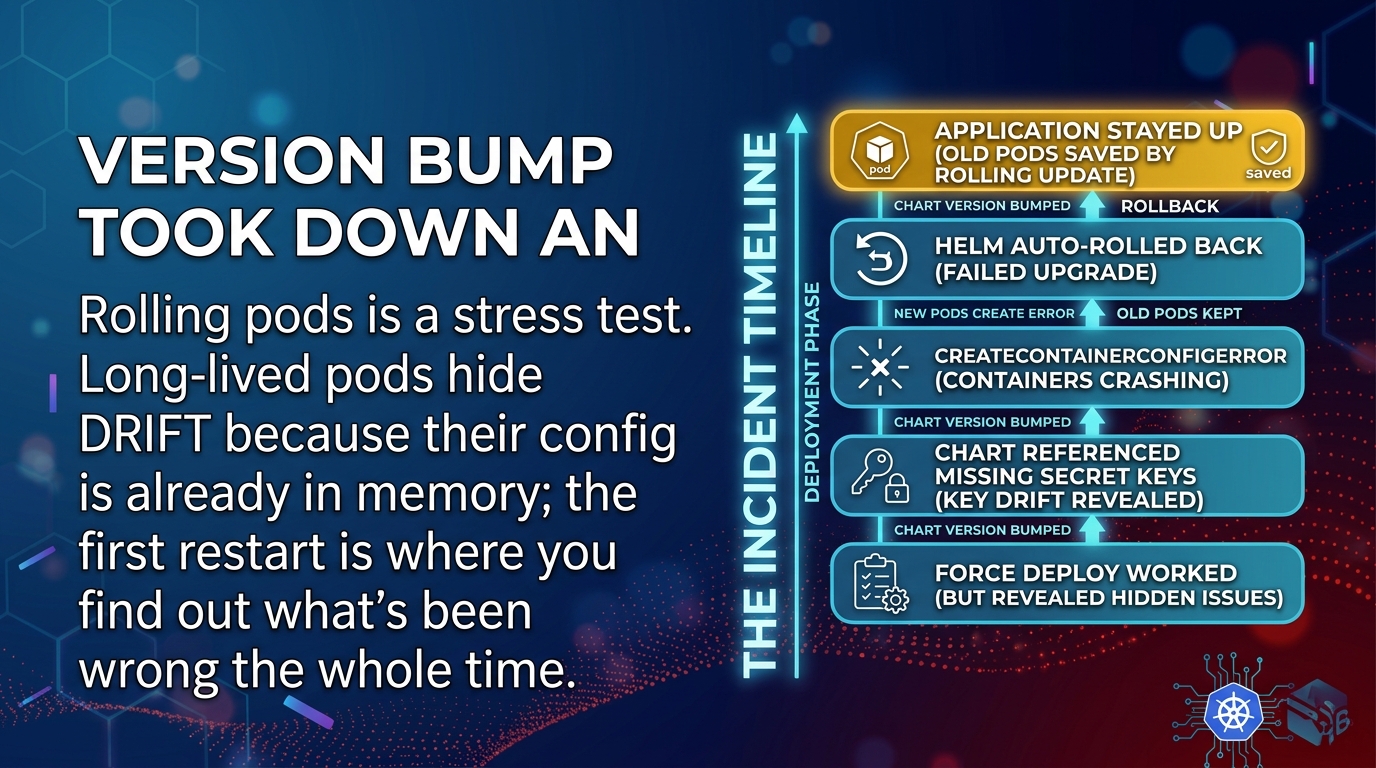
The version bump that took down an app (and how it self-healed)
One character of YAML, four pods that never started, and two safety nets I didn't know were holding. Every restart is an audit. Schedule them before they schedule you.
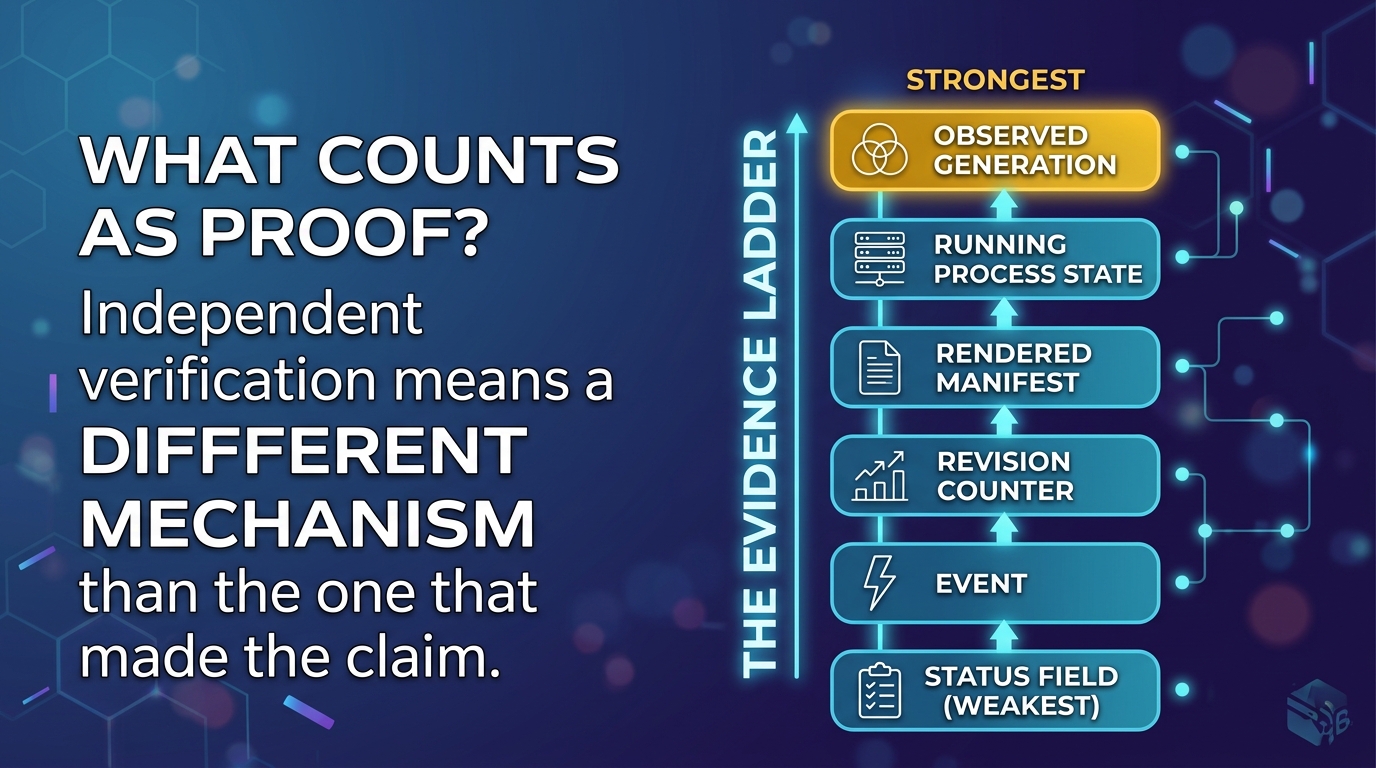
What counts as proof
"Verify your work" isn't an instruction. It's a mood. Here's the version that's an instruction. Verify with a different mechanism than the one that made the claim.
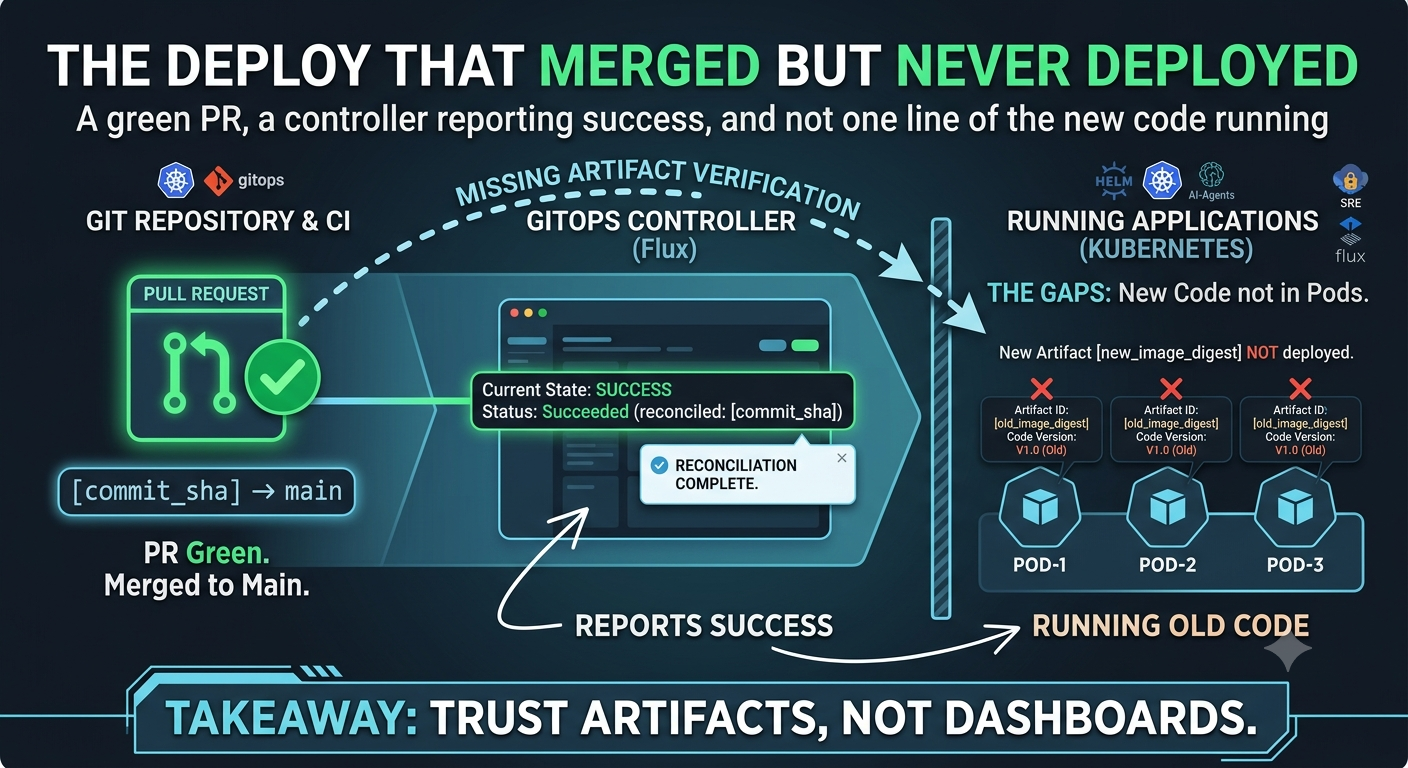
The deploy that merged but never deployed
A green PR, a controller reporting success, and not one line of the new code running